What clustering adds on top of partitioning
Partitioning by event_date turns a 4 TB table into roughly 130 GB days. That is the right first move, but not the last: a Looker explore that filters account_id = 8821 on today's partition still reads every clustered (or unclustered) block in that day if account_id is not in CLUSTER BY. You paid to skip 364 days and then bought the entire remaining day for one tenant.
-- events is PARTITION BY event_date, no CLUSTER BY
SELECT event_name, COUNT(*)
FROM `proj.analytics.events`
WHERE event_date = CURRENT_DATE()
  AND account_id = 8821;
-- Storage skips other days. Inside today, every block is read.
BigQuery clustering is block-level min/max metadata on the clustered columns, automatically maintained. It is not a second partition key and does not replace a date filter; it is what happens inside the partitions that survived pruning. If the date filter never reaches storage, clustering never gets a chance to help, because the job is already reading every day.
The mental model that fails is treating PARTITION BY as the complete layout. Partitioning is a coarse, cheap skip: whole folders of files. Clustering is a fine skip: blocks inside a folder whose min/max cannot contain the filter. Dashboards that always add account_id, status, or event_name after the date are exactly the jobs clustering is for; without it, every tenant scan is a full-day columnar read of the columns you selected. On-demand, that full-day read is bytes; on capacity, it is slot-ms and reservation pressure. Either way it shows up as a table that is 'already partitioned' in the design doc and still expensive in JOBS. The missing half is in DDL, CLUSTER BY, and SlashPeak looks for that half from real filter columns in job_stages, not from the column you liked in the ERD.
-- events is PARTITION BY event_date CLUSTER BY account_id, event_name
SELECT event_name, COUNT(*)
FROM `proj.analytics.events`
WHERE event_date = CURRENT_DATE()
  AND account_id = 8821;
-- Other days skipped by partition.
-- Blocks whose account_id min/max cannot contain 8821 skipped too.
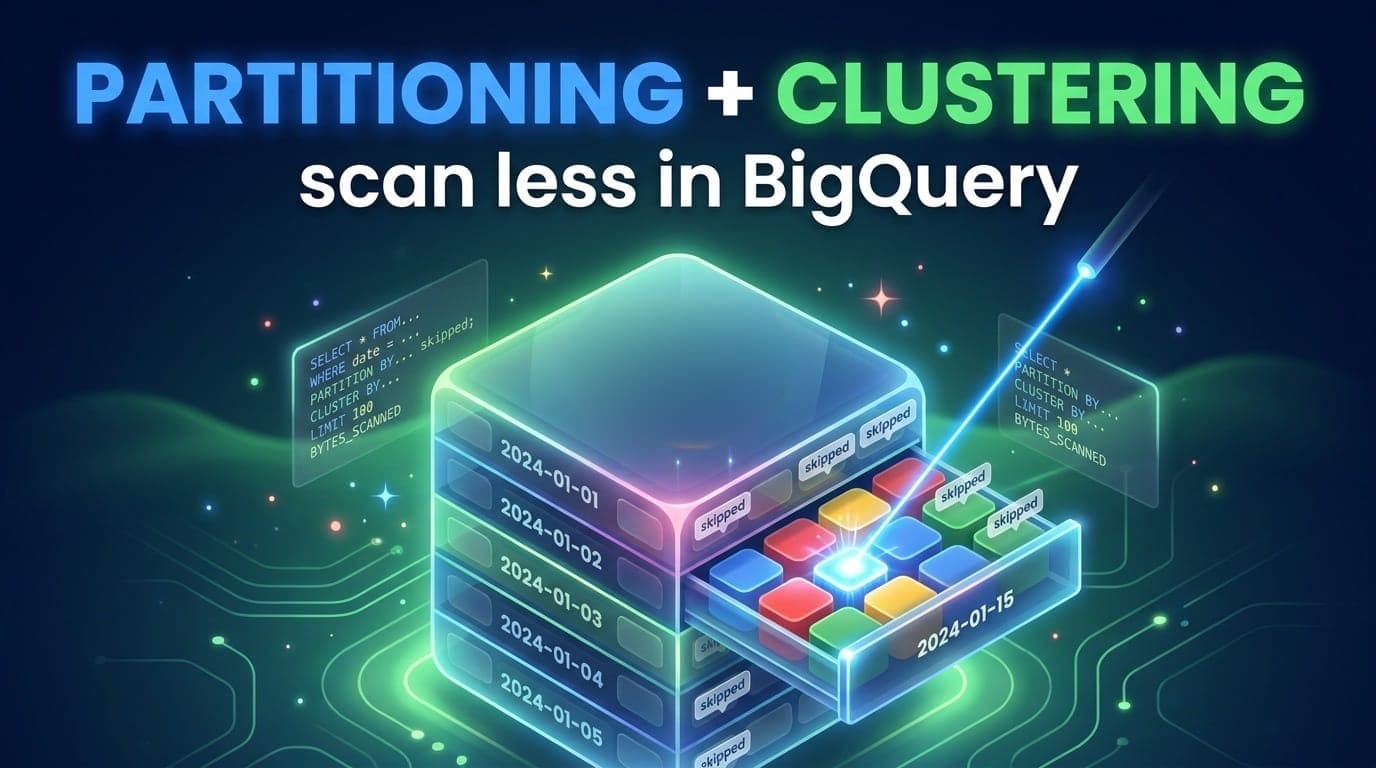
If you only remember one sentence: partitions skip days, clustering skips blocks inside those days, and a fact table that is queried by date and tenant usually needs both. The rest of this post covers which columns, in which order, when the table has neither, and how the two rules stay honest about dollars.
Clustering skips blocks inside the partitions that survived pruning
Partitioning by date still reads every block in that day if you filter on account_id with no CLUSTER BY. Clustering on the real filter columns lets BigQuery skip the rest.
Billed as waste
PARTITION BY date, no CLUSTER BY
All blocks in today's partition
After the fix
CLUSTER BY account_id, event_name
Only matching cluster blocks
Which columns actually belong in CLUSTER BY
SlashPeak's clustering recommendation does not guess from column names. It looks at high-usage filter and join columns on tables that are already queried enough to matter, and that do not already cluster on those columns. Cardinality has to be useful: clustering on a boolean is a no-op; clustering on a unique event_id is close to a second primary key and fights the date partition for the leading slot.
The usual winning pair is tenant or account, then event_name or status. Put the most selective equality filter first. BigQuery can skip blocks when the leading clustered column is filtered with equality, IN, or a tight range. A leading column that is almost always a wide range, or not filtered at all, wastes the metadata on the columns behind it.
CREATE TABLE `proj.analytics.events`
PARTITION BY event_date
CLUSTER BY account_id, event_name
AS SELECT * FROM `proj.analytics.events_heap`;

ALTER TABLE `proj.analytics.events`
CLUSTER BY account_id, event_name;
Usage is measured at the storage layer, not by grepping SQL. A column that appears in a SELECT list but never in a pushed filter is not a clustering candidate, and a column filtered after a JOIN in a way that never reaches the base READ is not a candidate either. That is why the rule walks job_stages: name-based guesses, like anything ending in _id, produce CLUSTER BY lists that look sophisticated and skip nothing.
You get four clustering columns. Using all four because you can is how you get none of them maintained well; two or three is enough for almost every fact table, and it is fine to leave a slot empty if the fourth candidate is a maybe. You can ALTER later, but you cannot easily undo a six-month-old CLUSTER BY that put event_id first because it was the primary key in the wiki. The partition column does not belong in CLUSTER BY either: it already has a stronger skip, and repeating it burns a cluster slot without helping the account filter behind it. SlashPeak excludes the partition column from candidates for that reason, and recommends what the expensive jobs already filter inside the day, not a second copy of the day.
-- Boolean leading column: two blocks, no skip
CLUSTER BY is_internal, account_id, event_name

-- Unique id first: min/max per block is almost a range of everything
CLUSTER BY event_id, account_id

-- Partition column repeated: burns a slot, does not help tenant filters
CLUSTER BY event_date, account_id
Clustering skips blocks inside a partition
Partitioning by date still reads every block in that day if you filter on account_id with no CLUSTER BY. Clustering on the real filter columns lets BigQuery skip the rest.
Billed as waste
Partitioned, not clustered
All blocks in the day · full column read
After the fix
CLUSTER BY account_id, event_name
Matching blocks only
- Leading column is the equality filter in the expensive jobs, not the column you like in the ERD.
- Two or three columns is enough. A six-column CLUSTER BY is how you get none of them maintained well.
- Reclustering is automatic on BigQuery; you do not VACUUM. You do still need the DDL.
- Do not put the partition column in CLUSTER BY. It already prunes at a coarser grain.
- Cardinality too low (boolean) or too high (row id as leading key) both fail to skip blocks.
The table that has neither
LARGE_UNPARTITIONED_TABLE is the advisory cousin: a large, actively queried table with no PARTITION BY and no CLUSTER BY. There is no dollar figure, because we will not invent a layout for you from metadata alone, but the finding is the prompt to pick one. An 800 GB orders heap queried on order_created_at belongs partitioned. A 200 GB dimension queried on account_id belongs clustered. A 2 TB events table usually wants both.
CREATE TABLE `proj.analytics.orders`
PARTITION BY DATE(order_created_at)
CLUSTER BY account_id
OPTIONS (require_partition_filter = TRUE)
AS SELECT * FROM `proj.analytics.orders_heap`;
The advisory exists because the SELECT date-filter rule only fires when an unpartitioned table already has a temporal column and a job that did not filter it. A heap with no timestamp, or a heap that is always filtered in SQL in a way that still reads everything, can sit outside that rule and still dominate the invoice. Size plus active queries plus zero layout is its own smell.
Do not cluster a 2 TB heap as the first move and call it done. Clustering without partitioning means every date-shaped query still considers the whole table's blocks. Partition first when a DATE, TIMESTAMP, or DATETIME column is what jobs already use. Cluster second on the equality filters that remain. The CREATE TABLE that does both in one pass is cheaper than two rewrites.
CREATE TABLE `proj.analytics.accounts`
CLUSTER BY account_id, region
AS SELECT * FROM `proj.analytics.accounts_heap`;
-- 200 GB of attributes. Equality lookups on account_id.
-- Date partitions would add operational cost without a date grain.
Dimensions are the exception that people over-partition. A 5 GB account table does not need PARTITION BY date. It may want CLUSTER BY account_id if it is 200 GB of slowly changing attributes and every fact join filters it. LARGE_UNPARTITIONED_TABLE uses a size floor so we do not nag you about small heaps. When it does fire, the table is big enough that layout is a project, not a style choice.
SlashPeak reads INFORMATION_SCHEMA for DDL and storage, never table contents. The advisory will not tell you which column to partition on. The clustering rule, once a table is partitioned or even while it is not, will tell you which filters already show up. Use both: advisory to start the layout ticket, recommendation to pick the CLUSTER BY list from real jobs.
A 2 TB heap vs. partition + cluster
Tables that grew up without a layout make every query and every MERGE more expensive. SlashPeak flags the gap as advisory — the dollar figure depends on which column you partition on.
Billed as waste
No PARTITION / CLUSTER
Every query reads the heap
After the fix
PARTITION BY date · CLUSTER BY key
Prune days, then skip blocks
Leading column, cardinality, and why order is the whole game
Clustering metadata is nested. Filters on the second column help only inside blocks that already matched the first. If you CLUSTER BY event_name, account_id and the expensive jobs filter account_id without event_name, you get little skip. Reverse it to account_id, event_name and the tenant filter can drop blocks before event_name is considered. Order is not a style choice; it is the access path.
-- DDL: CLUSTER BY event_name, account_id
SELECT COUNT(*)
FROM `proj.analytics.events`
WHERE event_date = CURRENT_DATE()
  AND account_id = 8821;
-- Second clustered column without the leading one:
-- block skip on account_id is weak or absent.

-- DDL you wanted:
-- CLUSTER BY account_id, event_name
Cardinality of the leading column should be high enough that a typical equality lands in a small fraction of blocks, and low enough that each block's min/max is a tight band rather than almost the whole domain. Account_id on a multi-tenant SaaS fact table is the textbook middle. A boolean is too low. A UUID event_id as leading column is often too high: each block contains a random smear of ids, min/max cannot exclude the next lookup, and you used your best slot.
IN lists and tight ranges on the leading column can still skip. Leading-column inequality across most of the domain cannot. If the only filter you have is event_name LIKE '%click%', clustering will not save you; fix the predicate or materialize a mart instead of adding a CLUSTER BY as a wish.
SELECT event_name, COUNT(*)
FROM `proj.analytics.events`
WHERE event_date BETWEEN @start_date AND @end_date
  AND account_id IN (8821, 8822, 9090)
  AND event_name = 'checkout';
-- Partition range on event_date.
-- Cluster skip on account_id, then event_name.
Joins use clustering too when the join key is the leading column and the probe side can prune. A fact clustered on account_id, joined to a 20-row account list, can skip blocks. A fact clustered on event_name, joined on account_id, cannot. SlashPeak counts columns that appear in storage-level filter substeps of READ stages, which is where pushed join predicates show up when they show up. If they never push, they never become a recommendation, correctly, because clustering on a column the plan never filters is dead DDL.
When two columns look tied on usage, pick the one with better equality selectivity as leading, and the one that is still useful as a second filter behind it. Do not alphabetize, and do not copy the primary key order from Postgres: the warehouse's CLUSTER BY is allowed to disagree with the OLTP key, and should disagree if the jobs disagree.
Partition pruning vs. a full table scan
Each tile is one day-partition. A predicate on event_date reads one tile. DATE(event_ts) or a missing filter reads all of them — same SQL intent, 30× the bytes.
Billed as waste
DATE(event_ts) = CURRENT_DATE()
30 / 30 partitions read · ~4 TB
After the fix
event_date = CURRENT_DATE()
1 / 30 partitions read · ~130 GB
What clustering cannot do
Clustering cannot fix a missing partition filter. If the job wraps DATE(event_ts) instead of comparing event_date, every partition is read, and clustering works, at best, inside all of them: still a full table scan with extra metadata, since partition pruning is the first half and clustering is the other half. It also cannot fix SELECT *, because block skip still reads the clustered columns you asked for; if you asked for two hundred columns including a 2 MB JSON payload, skipped blocks help but the blocks you do read are still wide. Projection and clustering are complementary: narrow the SELECT list first when the table is wide, then cluster.
-- PARTITION BY event_date CLUSTER BY account_id
SELECT COUNT(*)
FROM `proj.analytics.events`
WHERE DATE(event_ts) = CURRENT_DATE()
  AND account_id = 8821;
-- DATE(event_ts) is not the partition column.
-- Every day is read. Clustering never sees a single-day folder.
Clustering also cannot fix a MERGE that matches only on event_id. The MERGE target READ still needs a partition predicate; clustering on event_id may reduce some block reads inside a day, but it will not skip the other days. Layout does not substitute for DML predicates. If MERGE_REWRITE is firing, fix the ON clause first and come back to CLUSTER BY after the target is pruned.
Clustering cannot help predicates that never reach storage. A filter applied in a HAVING, or on an alias after a wrapping SELECT *, or inside a JavaScript UDF, will not consult min/max; the plan either shows a filter on the READ or it does not. SlashPeak only recommends columns that already appear there. If your favorite column never shows up, the jobs are not filtering it at the storage layer yet.
Clustering is also not partitioning on a second column. You cannot CLUSTER BY to get the operational benefits of partition expiration, partition-level DELETE, or require_partition_filter; those are partition features. If you need to drop data older than 90 days cheaply, you need PARTITION BY a date, not a wish that clustering will make expiration work.
The filter has to reach storage, not just the SQL
BigQuery only skips partitions when the optimizer can push a comparison on the partition column to the READ. Wrapping the column, or filtering a different timestamp, never gets there.
Billed as waste
WHERE DATE(event_ts) = CURRENT_DATE()
SQL
WHERE DATE(event_ts) = CURRENT_DATE()
Optimizer
Cannot fold onto event_date
Storage READ
All partitions · 4 TB billed
After the fix
WHERE event_date = CURRENT_DATE()
SQL
WHERE event_date = CURRENT_DATE()
Optimizer
Partition filter pushed down
Storage READ
1 partition · ~130 GB billed
ALTER TABLE CLUSTER BY versus recreate
ALTER TABLE … CLUSTER BY account_id, event_name is valid in BigQuery and is the usual incremental change. New data is clustered as it lands, while existing blocks recluster in the background. There is a window where queries see a mix of old heap layout and new clustered blocks, which is why you should not expect the first hour after ALTER to match the savings estimate.
CREATE TABLE … AS SELECT with the new PARTITION BY and CLUSTER BY, then swap names, is the move when you are also changing the partition column, adding require_partition_filter, or dropping columns. It is a rewrite you pay for once, cheaper than years of queries against the heap, but still a rewrite: schedule it like a backfill, not like a metadata toggle.
CREATE TABLE `proj.analytics.events_new`
PARTITION BY event_date
CLUSTER BY account_id, event_name
OPTIONS (require_partition_filter = TRUE)
AS
SELECT
  event_date,
  account_id,
  event_name,
  user_id,
  event_ts,
  props
FROM `proj.analytics.events`;

-- Swap in a maintenance window, then DROP events_old.
ALTER TABLE `proj.analytics.events`
SET OPTIONS (require_partition_filter = TRUE);
There is no VACUUM step. Automatic reclustering is part of the service. Your job is the DDL and the filter columns: watch storage and slot-ms after the change, and do not invent a maintenance job that rewrites the table every night to force clustering. That maintenance job is how you recreate MERGE_REWRITE on purpose.
Changing CLUSTER BY later is allowed and should be expected. Filter mix shifts when a new product surface lands, so re-run the recommendation after a quarter. If account_id falls off and device_id takes over, change the list; a CLUSTER BY that matched last year's Looker explores is not a forever contract.
Apply require_partition_filter in the same change set when you recreate. It does not cluster anything, but it stops the next intern from scanning the new beautifully clustered table without a date. Layout without guardrails is how you pay for the rewrite and then donate it to a console SELECT *.
Logical size is not what sits on disk
Nested, clustered event data often compresses 4× or more. Physical billing prices the compressed bytes. Logical billing prices the uncompressed ones — which is a tax if you compress well.
Logical · 10 TB
4× compression
Physical · 2 TB
How CLUSTERING_RECOMMENDATION ranks columns from the plan
The rule skips cache hits and jobs with no plan, and groups remaining jobs per table by normalized query hash so ten runs of the same explore count as one pattern, not ten votes. Tables below a size floor, with too few distinct patterns, or already at four cluster columns are skipped, so small tables and one-off notebooks do not get to design your layout. Candidate columns are DDL columns minus existing CLUSTER BY columns minus the partition column, and a pattern uses a column when that column appears in READ-stage storage-level filter substeps. Usage ratio is patterns that use the column divided by patterns on the table; only columns at or above the high-usage threshold are recommended, capped at remaining cluster slots.
-- Counted: pushed to the table READ
WHERE event_date = CURRENT_DATE()
  AND account_id = 8821
  AND event_name IN ('view', 'buy')

-- Not counted: never reaches storage min/max
WHERE UPPER(event_name) = 'VIEW'
WHERE JSON_VALUE(props, '$.account_id') = '8821'
HAVING account_id = 8821
Savings are conservative: a fraction of bytes from the union of jobs whose patterns use any recommended column, times on-demand list price. Clustering never skips as aggressively as a partition predicate, so the ratio is lower than the full-scan rule on purpose. The dollar figure is for ranking, not a guarantee that ALTER TABLE will print that check.
This is why the finding names columns. A ticket that says cluster the table is not actionable; a ticket that says account_id then event_name, from 80 percent of distinct patterns on a 2 TB table, is a DDL change you can review against the explores you know. If the named columns surprise you, open the representative jobs: either your mental model of the workload is stale, or a BI explore is filtering something you did not know about.
The scanner still will not cluster for you: it reads metadata only. You run the ALTER or the recreate, or, on Growth and above, let Cognis AI DBA add the columns with a separate operator key and owner approval (on a dbt model, it opens a pull request that a person merges). The next scan should drop the finding for those columns. If a new high-usage column appears, that is a new recommendation, not a failure of the last one.
SlashPeak trusts job_stages, not a grep of the query text
SQL can mention the partition column in a CTE that never hits the base read. The READ operator in the execution plan is the billed truth. SlashPeak flags only jobs that have that plan.
Query text
WHERE event_date = @d appears in a CTE
Looks filtered · often a false all-clear
WITH recent AS ( SELECT * FROM events WHERE event_date = @d ) SELECT * FROM events JOIN …
job_stages READ
Filter pushed to storage? yes / no
What SlashPeak scores · $/mo from bytes billed
READ $events filter: — records_read: 4.1e9
A practical layout order for a 2 TB events table
Stop the full-table SELECTs first. A CLUSTER BY on a table that every explore reads without event_date is rearranging deck chairs. Fix partition filters and require_partition_filter so jobs that survive are at least day-scoped, then look at what those surviving jobs filter inside the day.
Create or alter to PARTITION BY event_date CLUSTER BY account_id, event_name, or whatever two columns the recommendation named. Recreate if you also need to drop payload columns from the BI-facing table. Keep the raw heap for forensic queries; do not cluster and partition a 200-column SELECT * mart and expect miracles.
Point Looker and Sheets at the laid-out table or a slim mart on top of it, and leave ETL writing to events. If MERGE_REWRITE is still firing, add incremental_predicates in the same sprint, since layout does not replace DML predicates and a well-clustered 4 TB MERGE without a target date still rewrites the heap. Then re-scan: CLUSTERING_RECOMMENDATION should clear for those columns, and LARGE_UNPARTITIONED_TABLE should never have applied once you had PARTITION BY or CLUSTER BY. If it is still in the list, you altered a different table than the one in the finding; names in details.tableName are the source of truth, not the model you meant to change.
Revisit quarterly. New event_name values, new tenant mix, new explores. Clustering is cheap to adjust relative to a year of full-day scans. SlashPeak will keep ranking columns from the jobs you actually run, a better layout committee than the ERD.
Fix projection first, then cluster
Clustering a 20 TB table before stopping SELECT * just makes an expensive star cheaper to shuffle. Name the columns, put a contract view in front of BI, then CLUSTER BY the filters that remain.
- 01
List columns
- 02
Contract view for BI
- 03
CLUSTER BY filters
- 04
Re-check bytes billed
- Partition filters and require_partition_filter first, so clustering has a day to work inside.
- CLUSTER BY the high-usage equality columns the plan already shows, leading column first.
- Slim the BI table so skipped blocks are not still 200 columns wide.
- Fix MERGE target predicates in the same sprint if DML still rewrites the table.
- Re-scan and confirm the finding names the table you changed.
Takeaways
- Partitioning skips days. Clustering skips blocks inside those days. A tenant-filtered fact table usually needs both.
- CLUSTER BY the equality filters that already show up in expensive jobs: account_id before event_id, never a boolean as the lead.
- Column order is the access path. A filter on the second clustered column without the leading one will not skip like you think.
- Clustering cannot repair DATE(event_ts), SELECT *, or an unscoped MERGE. Those are other tickets.
- A large queried heap with neither layout is LARGE_UNPARTITIONED_TABLE: an advisory, not a made-up dollar amount.
- SlashPeak recommends cluster columns from storage-level filters in job_stages plus DDL, and excludes the partition column from the candidate list.
- ALTER TABLE CLUSTER BY is the incremental change; recreate when you are also changing partitions or projection. You do not VACUUM.
- Proof is the next scan after DDL, not the design doc that already said the table was partitioned.