Databricks cost optimization is next
SlashPeak will read system.query.history and system.compute.warehouses — bytes read, DBU-hours, file skipping stats — and never SELECT your user catalogs. Same ranked findings, dollar estimates, and you-apply-the-fix model.
Delta scans, not SQL folklore
Missing partition filters and wrap-the-column predicates are why 'we partitioned it' still reads every Parquet file. The scanner will use query history metrics, not a grep of the SQL.
SQL warehouse DBUs while nobody is querying
Serverless warehouses that auto-stop too slowly, classic warehouses left running overnight, and a Large warehouse a Looker explore never needed.
ZORDER and liquid clustering
Data skipping that never skips, ZORDER on the wrong columns, and liquid clustering that has not caught up with the write pattern.
Photon shuffle is a DBU multiplier
AQE helps, but a shuffle-heavy join on an un-ZORDERed key still burns Photon DBUs. Plan metrics in system tables already show it.
What the scanner will check
The Databricks-native cost scanner — join the waitlist
Delta full table scan
Queries whose bytes read stay near table size despite a filter that should have skipped files.
Idle SQL warehouse DBUs
Warehouse uptime with no query.history jobs, plus auto-stop that is too long.
ZORDER / liquid clustering gap
Tables whose data-skipping stats stay near zero on the columns dashboards actually filter.
Photon shuffle-heavy query
Shuffle bytes and Photon CPU on repeated jobs that a clustered join key would shrink.
SELECT * over-fetch
Wide Delta tables scanned with star when the dashboard used eight columns.
Partition filter miss
Hive-style partitions that the predicate never reached — the Databricks version of a missing partition filter.
Metadata only. Table contents stay put.
What we ask for
SELECT on system.query.history
Read query duration, bytes read, rows, warehouse id, and statement text fingerprints.
SELECT on system.compute.warehouses
SQL warehouse size, auto-stop, and DBU metering history.
What we never ask for
SELECT on user catalogs
Never requested. Table contents stay in Unity Catalog.
Get notified when Databricks scanning ships
We'll email you when the first Databricks warehouse can connect. Same metadata-only promise as BigQuery — catalog and query history only, never your table contents.
Join the Databricks waitlist
One email when it ships. Nothing else.
Databricks cost notes
All articles for this warehouse →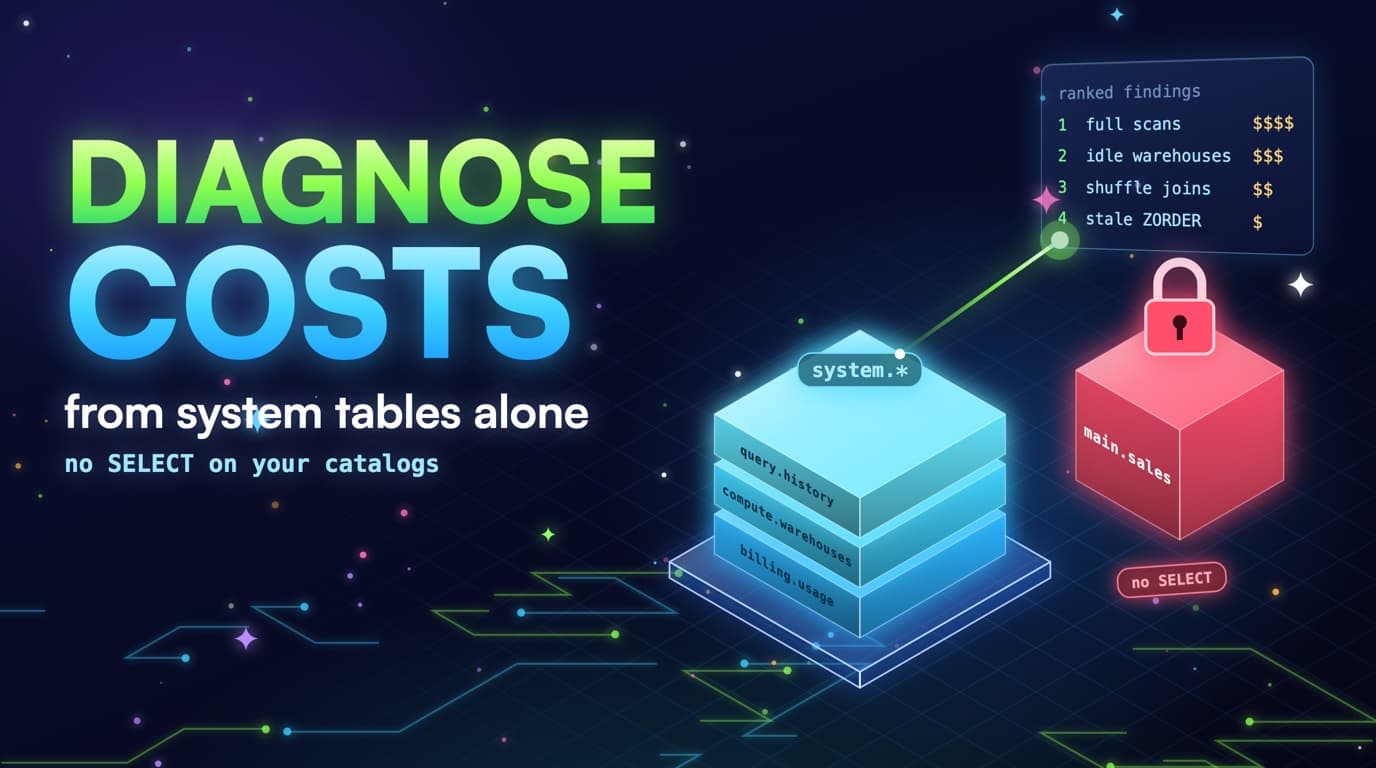
Diagnosing Databricks costs with system tables
system.query.history and system.compute.warehouses rank full scans, idle warehouses, and shuffle-heavy jobs. SlashPeak never needs SELECT on your tables.
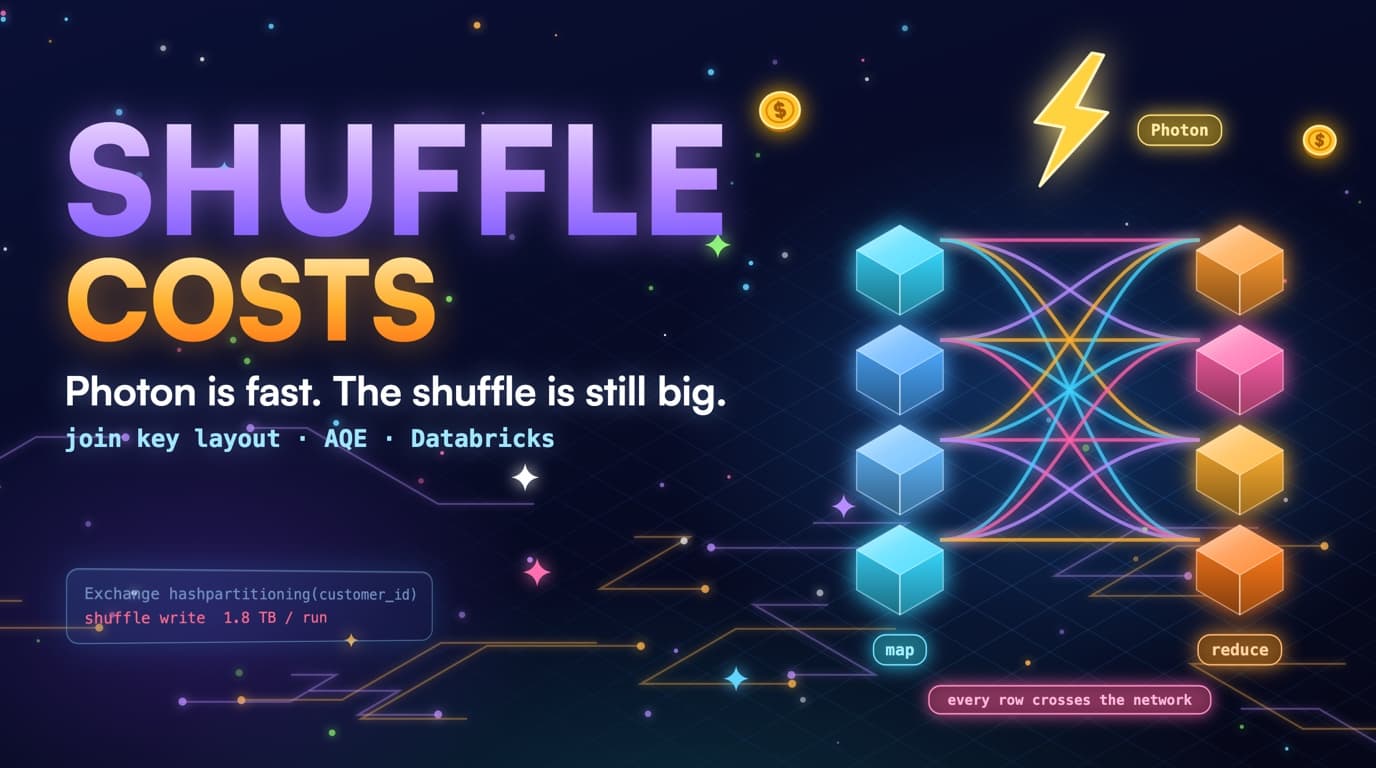
Databricks Photon shuffle costs and join key layout
Photon speeds up a shuffle join; it does not shrink it. Adaptive execution helps at the edges, but an unclustered join key still burns DBUs every run.
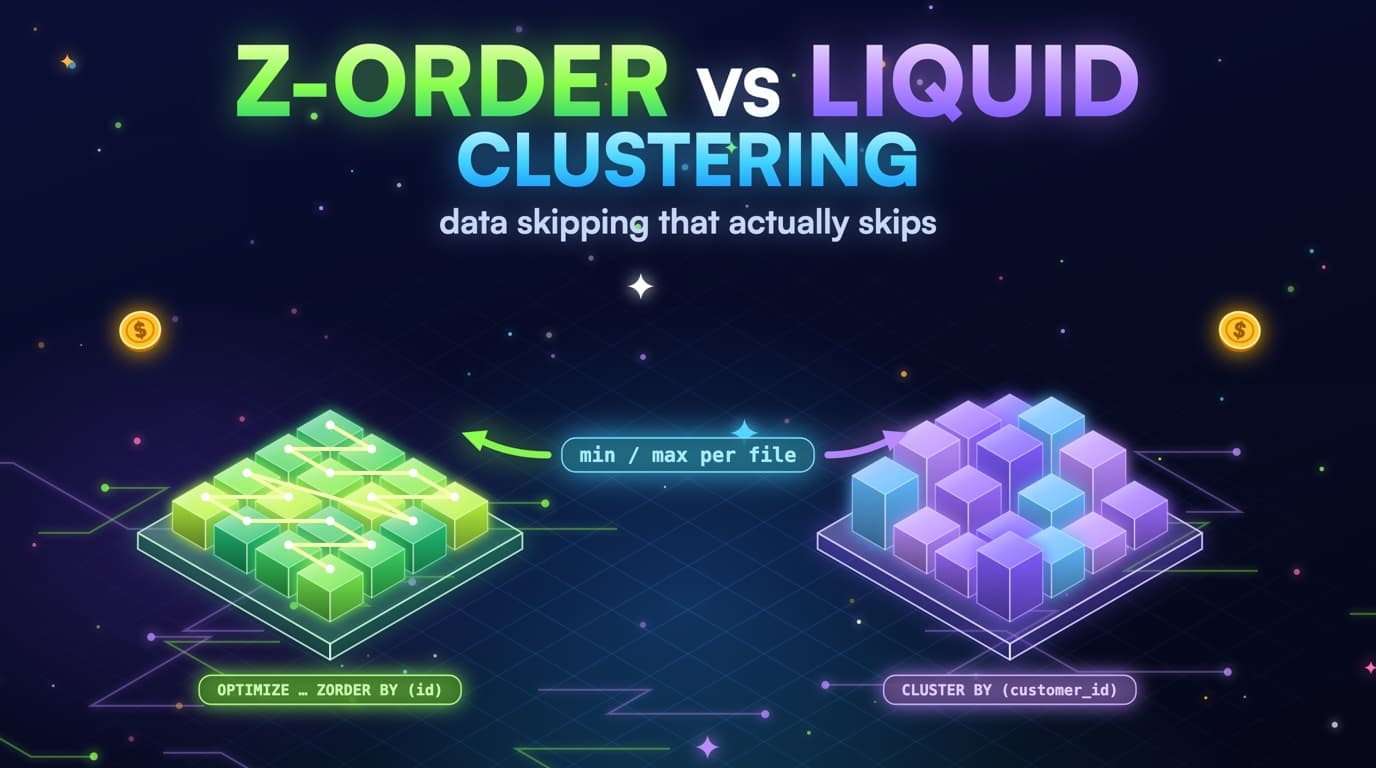
Z-ordering vs. liquid clustering in Databricks
ZORDER and liquid clustering write min/max stats so Photon can skip files. The wrong columns, or a stale table, means it still reads everything.
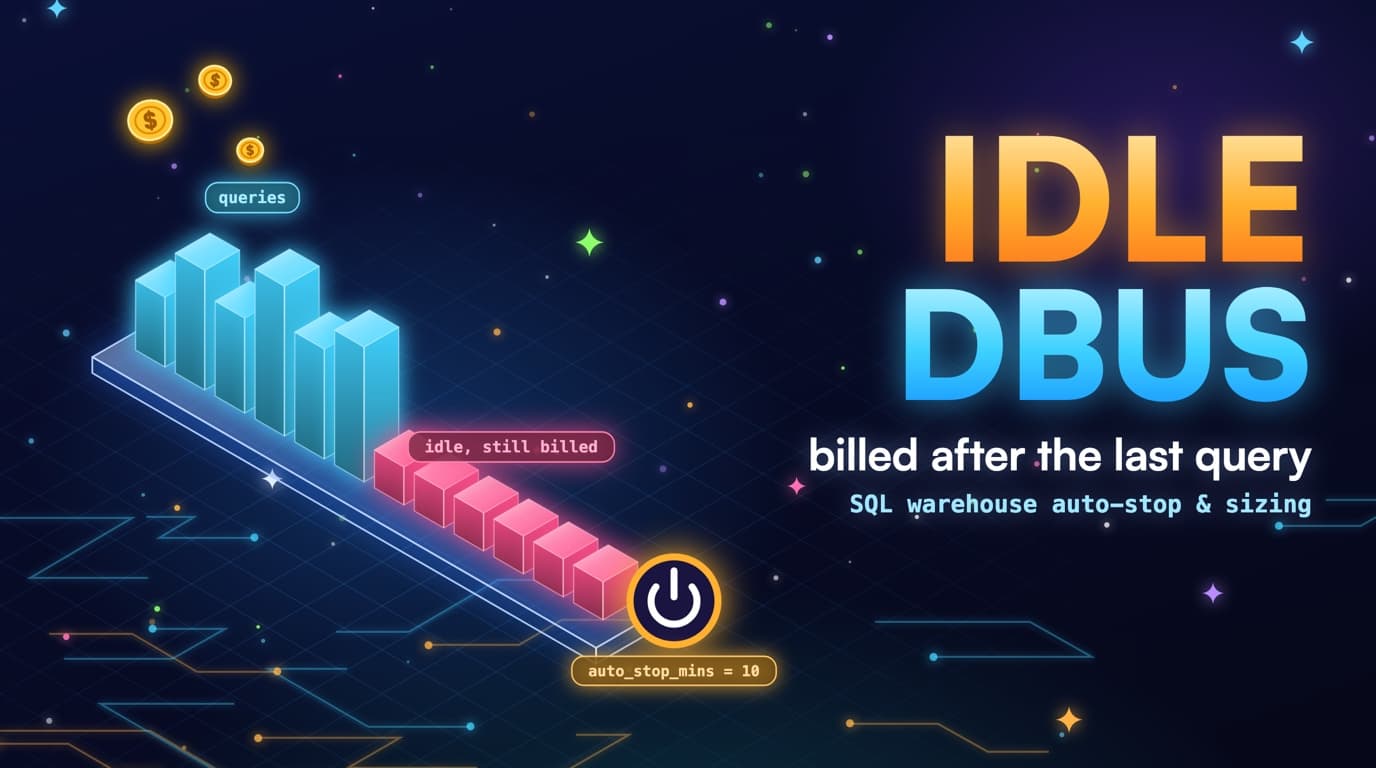
Databricks SQL warehouses: auto-stop and idle DBUs
A serverless warehouse with a 10-minute auto-stop bills 10 minutes after the last query. Oversizing is a separate leak, and system tables show both.
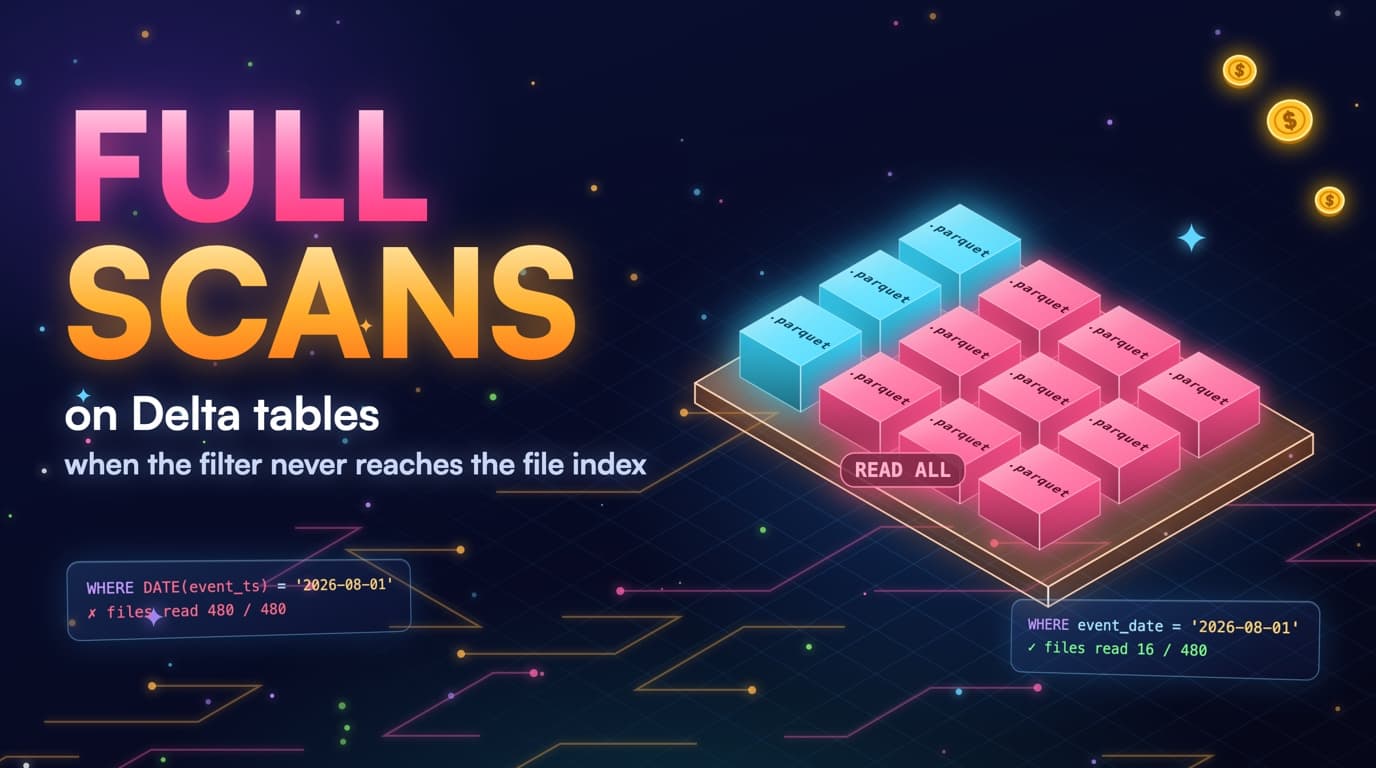
Databricks Delta full scans and missed file pruning
A Hive-style partition column only helps once the predicate reaches the file index. WHERE DATE(event_ts) still opens every Parquet file in the table.
Take control of your warehouse bill
Understand, reduce and govern your cloud data spend with SlashPeak — starting today.
- 30-day free trial
- No credit card
- Read-only access
- Set up in minutes