Snowflake cost optimization is next
SlashPeak will read ACCOUNT_USAGE and QUERY_HISTORY — bytes scanned, warehouse credits, clustering depth, and storage — and never SELECT your user tables. Same ranked findings, dollar estimates, and you-apply-the-fix model.
Micro-partitions, not SQL folklore
Clustering keys and wrap-the-column filters are why 'we clustered it' still scans 8 TB. The scanner will use QUERY_HISTORY bytes and partition stats, not a grep of the query text.
Warehouse credits while nobody is querying
Auto-suspend that is 10 minutes too long, an XL warehouse a dashboard never needed, and multi-cluster min that never scales to zero — three different credit leaks.
Clustering depth vs Search Optimization
Automatic clustering that never converges, and Search Optimization Service billed on tables whose predicates would have pruned anyway.
Time Travel you still pay for
DATA_RETENTION_TIME_IN_DAYS plus Fail-safe is a storage line item. Transient tables and zero-copy clones have different meters — the catalog already knows.
What the scanner will check
The Snowflake-native cost scanner — join the waitlist
Micro-partition prune miss
Queries whose bytes_scanned stay near table size despite a filter that should have pruned.
Idle warehouse credits
WAREHOUSE_METERING_HISTORY hours with no QUERY_HISTORY jobs, plus auto-suspend that is too long.
Clustering depth
Tables whose clustering depth stays high while automatic clustering credits keep burning.
Time Travel / Fail-safe storage
Retention days and Fail-safe bytes on tables nobody has queried.
Warehouse size mismatch
Dashboards on XL/2XL whose QUERY_HISTORY shows low parallelism and short runtime.
Search Optimization waste
SOS enabled on tables whose predicates already prune, or missing where point lookups scan everything.
Metadata only. Table contents stay put.
What we ask for
IMPORTED PRIVILEGES on SNOWFLAKE
Read ACCOUNT_USAGE views: QUERY_HISTORY, WAREHOUSE_METERING_HISTORY, TABLE_STORAGE_METRICS, clustering depth.
MONITOR USAGE (or equivalent)
Warehouse credit history and storage billing metadata.
What we never ask for
SELECT on user databases
Never requested. Table contents stay in the account.
Get notified when Snowflake scanning ships
We'll email you when the first Snowflake warehouse can connect. Same metadata-only promise as BigQuery — catalog and query history only, never your table contents.
Join the Snowflake waitlist
One email when it ships. Nothing else.
Snowflake cost notes
All articles for this warehouse →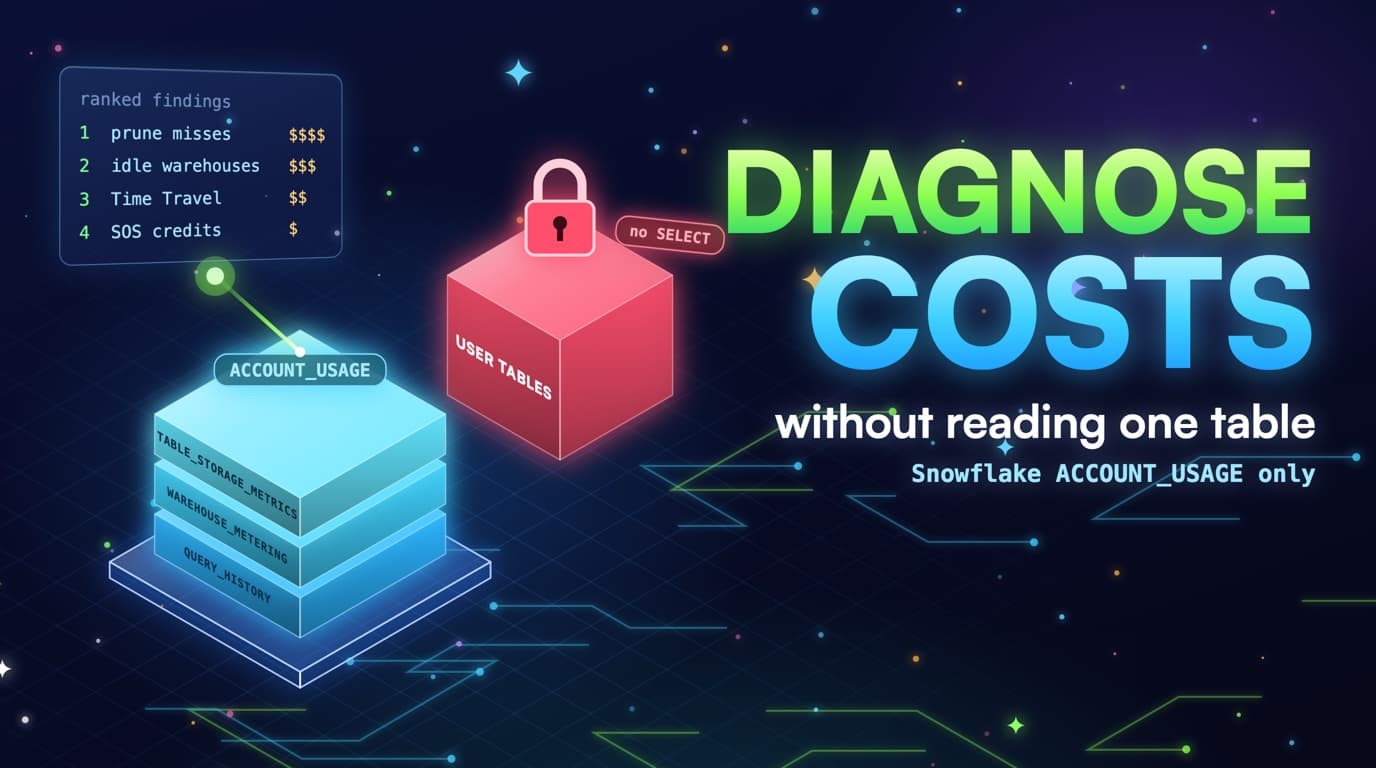
Diagnosing Snowflake costs with ACCOUNT_USAGE
QUERY_HISTORY, WAREHOUSE_METERING_HISTORY, and clustering views rank prune misses, idle warehouses, and Time Travel without SELECT on a single user table.
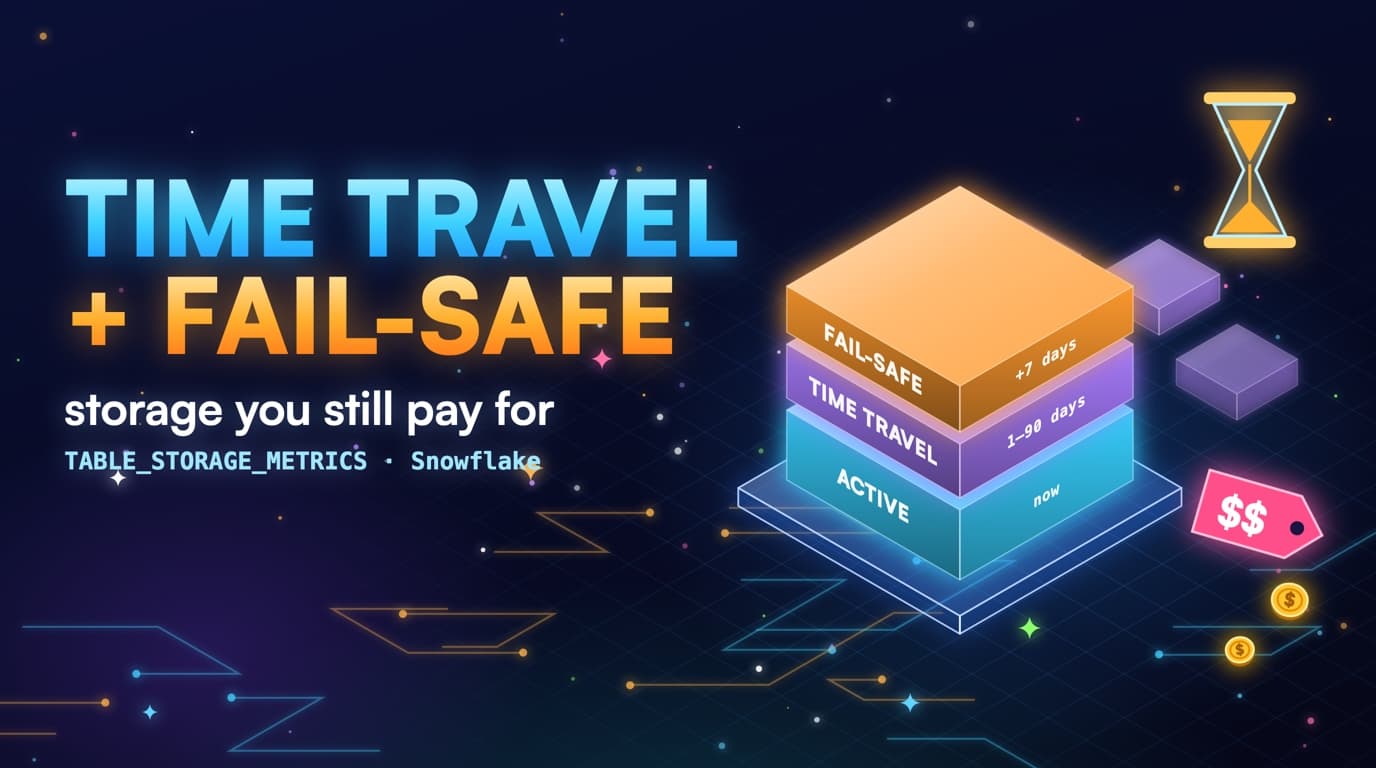
Snowflake Time Travel and Fail-safe storage costs
DATA_RETENTION_TIME_IN_DAYS plus Fail-safe outlives the query it protected. Transient tables skip Fail-safe. TABLE_STORAGE_METRICS splits the bill.
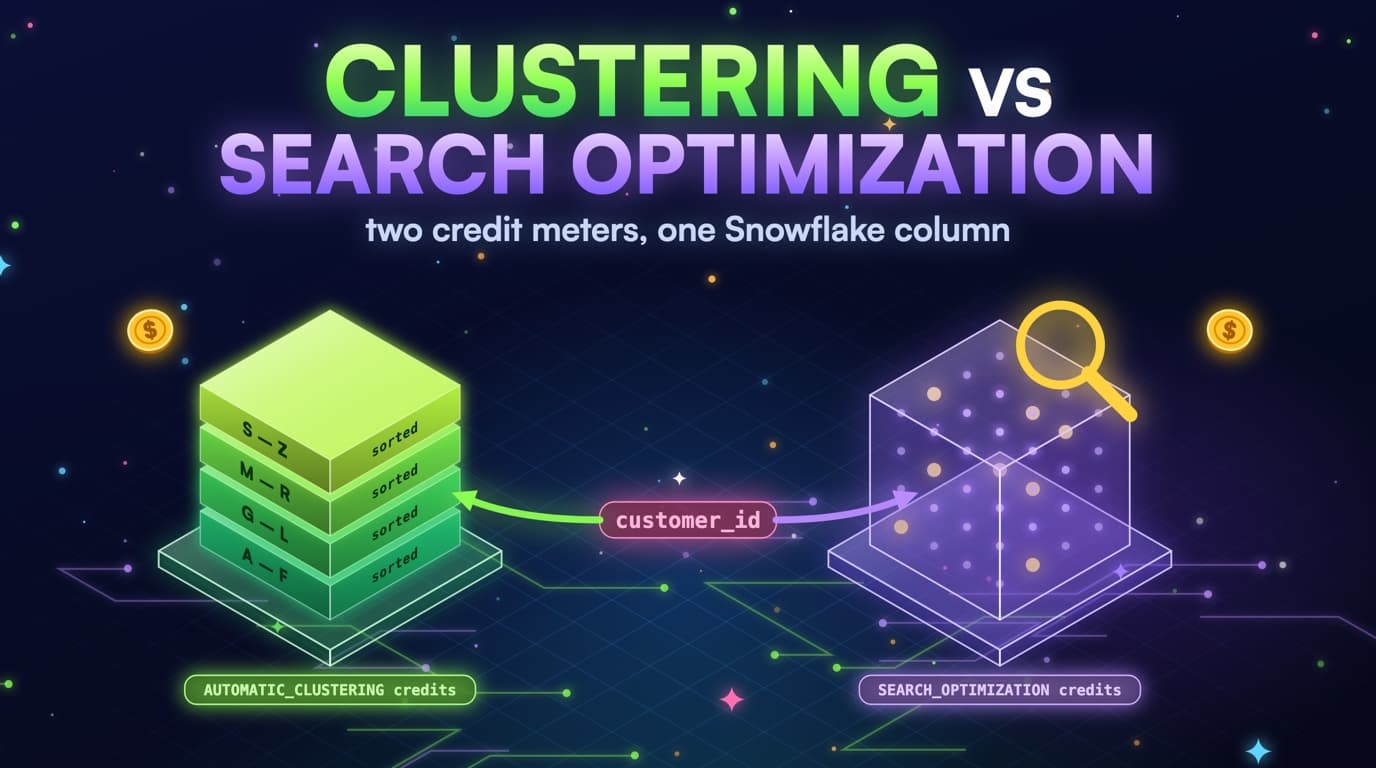
Snowflake clustering vs. Search Optimization
Automatic Clustering rewrites partitions for range pruning. Search Optimization is a separate path with its own credits. The wrong table pays for both.
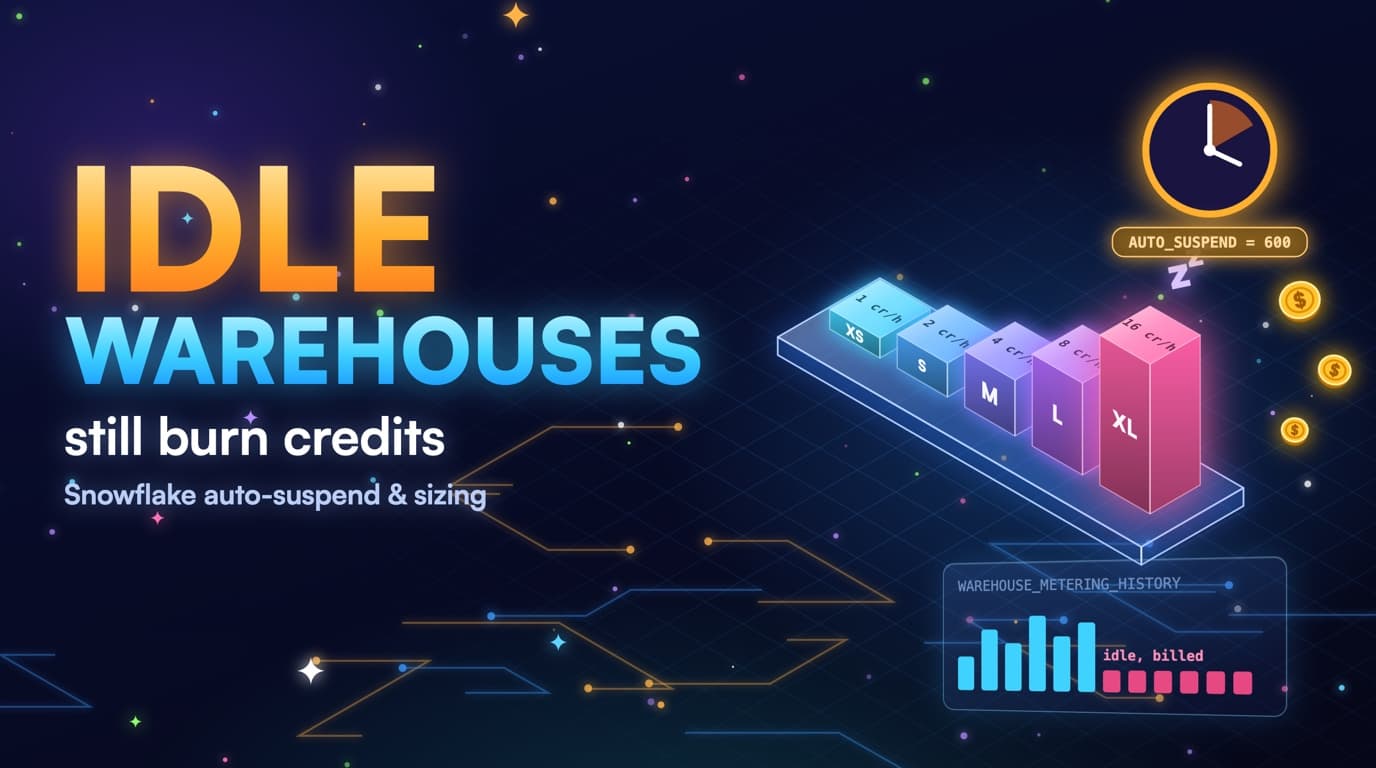
Snowflake idle warehouses: auto-suspend and sizing
Auto-suspend at 10 minutes bills for 10 minutes after the last query. WAREHOUSE_METERING_HISTORY shows the idle tail and the oversized warehouse behind it.
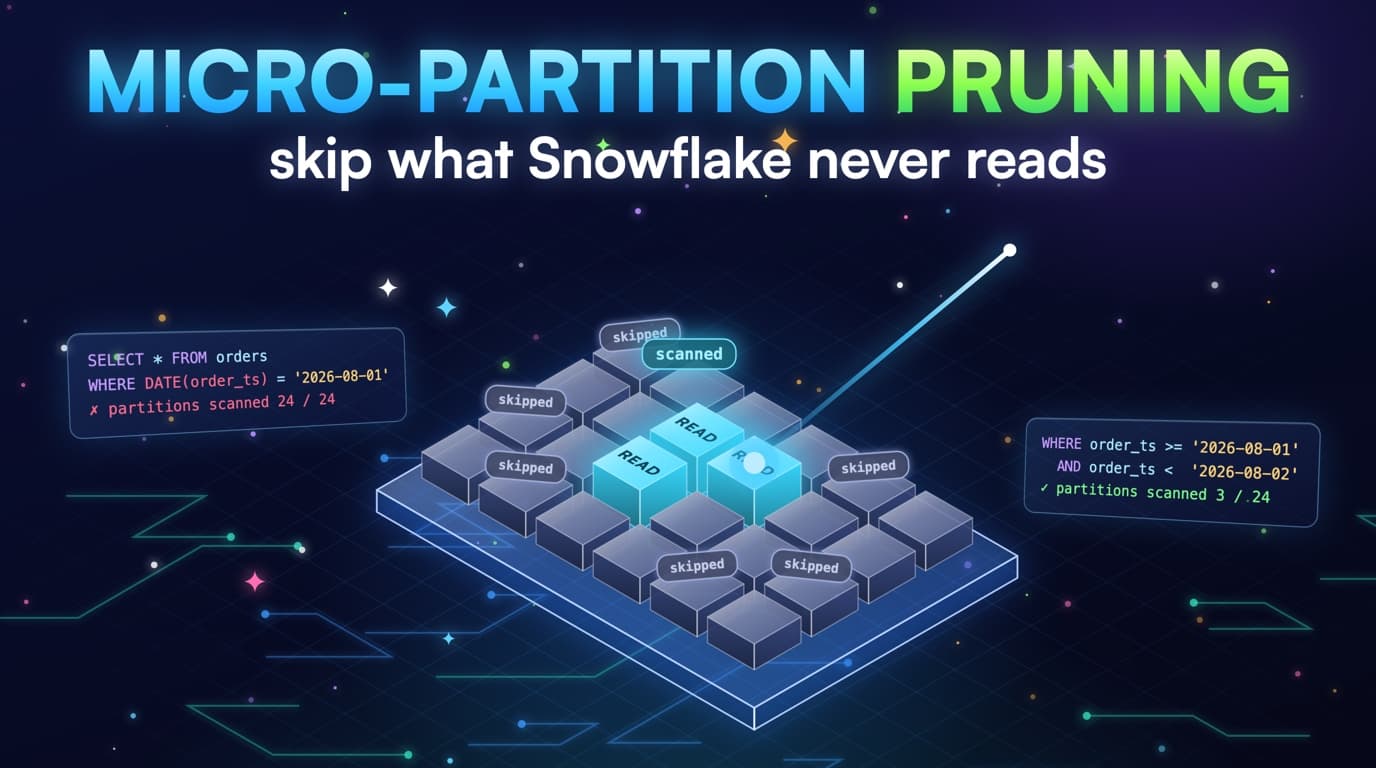
Snowflake clustering keys and micro-partition pruning
A CLUSTER BY key isn't a partition. Snowflake skips micro-partitions by min/max metadata; a wrapped predicate like DATE(order_ts) can't use it.
Take control of your warehouse bill
Understand, reduce and govern your cloud data spend with SlashPeak — starting today.
- 30-day free trial
- No credit card
- Read-only access
- Set up in minutes