Credits accrue while the warehouse is up, not while busy
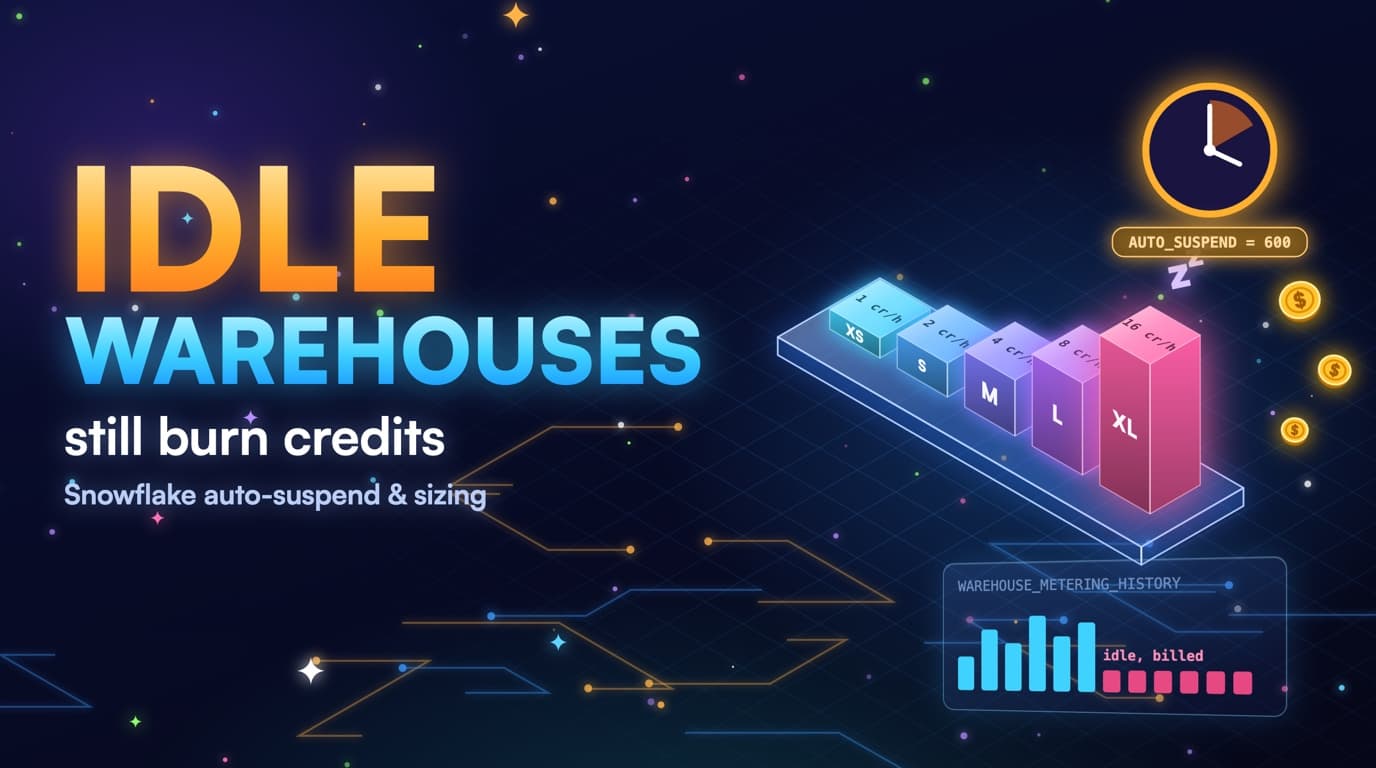
Snowflake warehouses bill per second with a 60-second minimum once resumed, so auto-suspend of 10 minutes means every Looker explore that ran for 8 seconds still bought 10 minutes of XL credits: forty explores a day isn't forty query runtimes, it's forty suspend tails stacked on the work. WAREHOUSE_METERING_HISTORY credits_used with no overlapping QUERY_HISTORY rows is idle, a different finding from a query that scanned 8 TB, and mixing the two in one 'Snowflake is expensive' Slack thread is how the wrong fix gets applied.
SELECT warehouse_name, SUM(credits_used) AS credits
FROM snowflake.account_usage.warehouse_metering_history
WHERE start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
GROUP BY 1
ORDER BY 2 DESC;
-- Join to QUERY_HISTORY on warehouse_name + overlapping window.
-- Credits with no queries in the hour are the suspend tail.
The meter is easy to ignore because the UI shows queries, not gaps. A resumed warehouse burns credits at its size even if the last query finished nine minutes ago and the next hasn't started. SHOW WAREHOUSES lists auto_suspend, size, and cluster counts; ACCOUNT_USAGE.WAREHOUSE_METERING_HISTORY lists credits_used by hour, none of it requiring table contents to see that ANALYTICS_XL is awake around the clock.
An X-Large runs 16 credits per hour, so ten minutes of idle after an 8-second explore is about 2.7 credits of almost pure suspend tail; forty explores a day is on the order of a hundred credits a day, three thousand a month, before the queries themselves. Shrinking auto-suspend to 60 seconds doesn't make the explore faster, it just stops buying the other nine minutes. Cloud services credits are a third line on the same view, usually small next to compute, but when they're not (compilation storms, metadata-heavy SHOW, constant resumes) they belong on a ranked list of their own: compute idle, scan waste, and cloud services are three separate fixes with three separate owners.
SlashPeak will rank idle credits separately from prune misses once the Snowflake scanner ships. Until then, the join you want is metering hours versus query hours: if an hour billed and no QUERY_HISTORY row overlaps the warehouse, that hour is idle; if it billed and queries ran the whole time, look at size and scan shape instead.
A warehouse's running-to-suspended cycle
Snowflake bills credits for every second a warehouse is resumed, whether a query is running or the auto-suspend timer is just counting down.
Auto-suspend is a product setting, not a suggestion
60 seconds is the usual first move for BI warehouses running short queries; ETL warehouses running 20-minute jobs can stay at 5 to 10 minutes so they don't resume-thrash. Multi-cluster MIN=1 MAX=3 that never scales to zero is a third leak: you paid for a floor you didn't need. SHOW WAREHOUSES already has auto_suspend and size, no table contents needed to see that ANALYTICS_XL is an X-Large with a 600-second suspend.
ALTER WAREHOUSE analytics_bi SET
  WAREHOUSE_SIZE = 'MEDIUM'
  AUTO_SUSPEND = 60
  AUTO_RESUME = TRUE
  MIN_CLUSTER_COUNT = 1
  MAX_CLUSTER_COUNT = 2;
Resume-thrash is the failure mode people cite for leaving auto-suspend at 10 minutes: if a warehouse suspends and a query arrives 15 seconds later, you pay another 60-second minimum plus a resume delay. Plot QUERY_HISTORY start times to check. If explores arrive every 20 seconds during business hours, 60 seconds still collapses the gaps; if they arrive once every 12 minutes, 600 seconds is buying eleven idle minutes per hit. Inter-arrival time is the real setting, not a default copied from a blog.
WITH starts AS (
  SELECT warehouse_name,
         start_time,
         LAG(start_time) OVER (
           PARTITION BY warehouse_name ORDER BY start_time
         ) AS prev_start
  FROM snowflake.account_usage.query_history
  WHERE start_time >= DATEADD(day, -7, CURRENT_TIMESTAMP())
    AND warehouse_name IS NOT NULL
)
SELECT warehouse_name,
       APPROX_PERCENTILE(DATEDIFF('second', prev_start, start_time), 0.5) AS p50_gap_s,
       APPROX_PERCENTILE(DATEDIFF('second', prev_start, start_time), 0.9) AS p90_gap_s
FROM starts
WHERE prev_start IS NOT NULL
GROUP BY 1
ORDER BY 1;
AUTO_RESUME should stay TRUE on BI warehouses; turning it off so nobody accidentally wakes an XL is a process smell, since the size and suspend are wrong, or the warehouse shouldn't exist. ETL warehouses on scheduled jobs can auto-resume too, since the schedule is the resume, but humans logging in to start a warehouse 'just for this backfill' is how an XL stays up until Friday. Statement timeouts and session idle aren't auto-suspend either: a hanging query holds the warehouse until the statement times out, so fix the SQL or statement_timeout_in_seconds rather than lengthening auto-suspend to hide a stuck query.
Account-level defaults won't save you. Warehouses created from a Terraform module with auto_suspend = 600 stay at 600 until someone ALTERs them. Audit SHOW WAREHOUSES (or ACCOUNT_USAGE warehouse event history) the same way you'd audit CLUSTER BY: documented intent and running setting tend to diverge within a quarter.
Pick auto-suspend from the query gap, not a default
Inter-arrival time, not a copied default, decides whether a shorter auto-suspend saves credits or just causes repeated 60-second minimums.
Warehouse size is a cost model
Bigger is faster until it isn't: a dashboard that scanned 80 MB doesn't get 16x faster on a 2XL, it gets a 16x meter on the same 60-second minimum. QUERY_HISTORY.EXECUTION_TIME against BYTES_SCANNED tells you whether the warehouse is compute-bound or just oversized. Separate ETL and BI too: a dbt run that wants Large shouldn't share a warehouse with 200 Looker users, or you'll either oversize for the dashboard or queue the transform.
Snowflake warehouse sizes double credits each step: Small is 2 credits per hour, Medium 4, Large 8, XL 16, 2XL 32. Latency doesn't double the other way for short, small scans. An 80 MB Looker tile is mostly compilation plus a tiny scan, so moving it from XL to Medium often keeps the tile under a second and cuts the minimum-minute cost fourfold, while moving a 20-minute hash-heavy transform from Large to XL might cut runtime in half and pay for itself. Measure it rather than standardizing on XL because that was the screenshot in onboarding.
Queued provisioning and queued overload in QUERY_HISTORY signal that size or max_cluster_count is too small for the concurrency you have; near-zero queueing with short execution_time means you're oversized, not compute-bound. If they spike every weekday at 9:00, consider a second cluster rather than a 2XL that sits idle at 10:15. Query Acceleration Service is a separate credit stream for spilling, not a substitute for the right size: enable it where QUERY_HISTORY shows spill on a warehouse you've already sized honestly, not to paper over a prune miss.
You apply ALTER WAREHOUSE; Snowflake won't notice on its own that ANALYTICS_XL hasn't had a query over 2 GB in 30 days. SlashPeak will flag a size-versus-bytes/runtime mismatch from metadata once the scanner ships, but the ALTER is still yours.
Credits per hour double with each warehouse size
Latency doesn't double the other way for small, short scans: moving an 80 MB dashboard tile from XL to Medium can cut the meter fourfold without making the tile noticeably slower.
- Idle: metering hours with no QUERY_HISTORY overlap. Shorten auto-suspend.
- Oversized: short jobs, small bytes, Large or bigger. Drop a size and re-measure.
- Multi-cluster floor: MIN_CLUSTER_COUNT > 1 with no concurrency to show for it.
The meter is often the waste, not the SQL
Fixing DATE(order_ts) still matters, but it doesn't replace a warehouse that never sleeps; treat capacity as its own ranked list: suspend tail, size mismatch, multi-cluster floor. A prune fix that cuts an 11-minute scan to 20 seconds helps the warehouse meter, but it's a trap if auto-suspend stays at 10 minutes, since you've just turned a busy warehouse into an idle one with a longer tail relative to the work it does. Revisit suspend after fixing scans; the two findings interact, but they're still two findings.
Resource monitors aren't auto-suspend. A monitor that suspends the warehouse at 80% of a monthly credit quota is a circuit breaker; it doesn't stop the 10-minute tail on every explore. Use monitors so a runaway 4XL can't melt the month, auto-suspend so the warehouse isn't billing while nobody's querying, and size so the warehouse that is querying isn't 16x what the SQL needs.
Snowpark, notebooks, and Streamlit apps that hold a session open keep a warehouse resumed until the session ends, which looks idle in QUERY_HISTORY (no SQL) and busy in metering; hunt those with SESSIONS or client application id and a human conversation, not a smaller auto-suspend that fights an open notebook. The ranked list belongs in the same place as query waste: dollars per month, owner, next ALTER. Mixing 'Snowflake is expensive' into one ticket is how the team resizes the wrong warehouse and leaves ANALYTICS_XL at 600 seconds.
Join metering to queries: the idle hour test
WAREHOUSE_METERING_HISTORY bills in one-hour (or shorter) windows with credits_used. QUERY_HISTORY has start_time and end_time. An hour where credits_used is material and the count of overlapping successful queries is zero is idle. An hour with queries whose total execution_time is a few seconds and credits that look like a full size-hour is a suspend tail hiding inside the hour.
WITH metering AS (
  SELECT warehouse_name, start_time, end_time, credits_used_compute
  FROM snowflake.account_usage.warehouse_metering_history
  WHERE start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
    AND credits_used_compute > 0
),
queries AS (
  SELECT warehouse_name, start_time, end_time
  FROM snowflake.account_usage.query_history
  WHERE start_time >= DATEADD(day, -31, CURRENT_TIMESTAMP())
    AND warehouse_name IS NOT NULL
)
SELECT m.warehouse_name,
       DATE_TRUNC('day', m.start_time) AS day,
       SUM(m.credits_used_compute) AS compute_credits,
       SUM(IFF(q.warehouse_name IS NULL, m.credits_used_compute, 0)) AS idle_credits
FROM metering m
LEFT JOIN queries q
  ON q.warehouse_name = m.warehouse_name
 AND q.start_time < m.end_time
 AND q.end_time > m.start_time
GROUP BY 1, 2
ORDER BY idle_credits DESC;
Don't over-fit the join. Clock skew and ACCOUNT_USAGE lag of up to a few hours will create false idle if you run this on 'the last 45 minutes.' Use a 7- or 30-day window and ignore the most recent lag; missing QUERY_HISTORY for a warehouse you just created is not a finding.
credits_used_compute is the warehouse. credits_used_cloud_services is the cloud-services share, which Snowflake may offset. Rank on compute first; if cloud services dominate, look at compilation, information-schema storms, and resume frequency rather than size.
WAREHOUSE_LOAD_HISTORY is the sibling view: avg_running, avg_queued_load, avg_queued_provisioning, avg_blocked. High running plus high credits is work. Near-zero running plus high credits is idle. High queued_load is a size or max_cluster problem, not a suspend problem. Read both views before you ALTER.
SELECT warehouse_name,
       AVG(avg_running) AS avg_running,
       AVG(avg_queued_load) AS avg_queued,
       AVG(avg_queued_provisioning) AS avg_provisioning
FROM snowflake.account_usage.warehouse_load_history
WHERE start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
GROUP BY 1
ORDER BY 2 DESC;
This join never needs SELECT on user databases. IMPORTED PRIVILEGES on SNOWFLAKE is enough to read ACCOUNT_USAGE, which is the grant SlashPeak will ask for, not warehouse ownership or the ability to ALTER WAREHOUSE on your behalf.
Multi-cluster MIN that never scales to zero
Multi-cluster warehouses add a floor. MIN_CLUSTER_COUNT = 2 means two XL clusters can be billed when the warehouse is resumed, even if concurrency never needed the second. MAX_CLUSTER_COUNT caps the spike; the leak is a MIN above 1 with QUERY_HISTORY showing cluster_number rarely above 1.
Standard versus economy scaling policy changes how fast Snowflake spins up clusters. Economy is cheaper and slower to scale; standard is snappier and easier to over-provision if MIN is already 2. Pick the policy after looking at queued_load, not before.
BI at 9:00 on Monday might justify MAX=3 and MIN=1 with auto-suspend 60. That combination scales out for the standup dashboards and scales to zero by 9:20. MIN=3 all day is a reserved-instance fantasy on a product that already bills per second.
QUERY_HISTORY.CLUSTER_NUMBER tells you whether the second cluster ever ran. If it's always 1, MAX greater than 1 is insurance you haven't used in 30 days; keep MAX if you have a known event and drop MIN to 1. If cluster_number hits 3 every morning and queued_load is still high, MAX is the conversation, not MIN.
SELECT warehouse_name,
       cluster_number,
       COUNT(*) AS queries,
       SUM(execution_time) / 1000 / 3600 AS execution_hours
FROM snowflake.account_usage.query_history
WHERE start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
  AND cluster_number IS NOT NULL
GROUP BY 1, 2
ORDER BY 1, 2;
You can't see MIN_CLUSTER_COUNT in every ACCOUNT_USAGE version as a clean column; SHOW WAREHOUSES and your Terraform state are the source of truth for the setting. Metering plus cluster_number tells you whether the setting earned its keep. SlashPeak will treat a multi-cluster floor with no concurrency as its own finding, not mixed in with auto-suspend idle time.
A multi-cluster floor you never use
MIN_CLUSTER_COUNT above 1 bills a second cluster at every resume. CLUSTER_NUMBER in QUERY_HISTORY says whether that second cluster ever actually ran.
Split ETL and BI before you buy a bigger box
A shared warehouse optimizes for neither workload. dbt wants a Large that stays up for 40 minutes; Looker wants a Medium that sleeps in 60 seconds. Share them and you get an XL that sleeps in 10 minutes and queues the transform while 200 explores compile.
Create two warehouses, named for the workload rather than team politics: ETL_LARGE, BI_MEDIUM. Point dbt at the first and BI tools at the second, and copy the same database role grants to both. An extra warehouse object costs nothing; a shared XL costs the whole bill.
CREATE WAREHOUSE etl_large
  WAREHOUSE_SIZE = 'LARGE'
  AUTO_SUSPEND = 300
  AUTO_RESUME = TRUE
  MIN_CLUSTER_COUNT = 1
  MAX_CLUSTER_COUNT = 1
  INITIALLY_SUSPENDED = TRUE;

CREATE WAREHOUSE bi_medium
  WAREHOUSE_SIZE = 'MEDIUM'
  AUTO_SUSPEND = 60
  AUTO_RESUME = TRUE
  MIN_CLUSTER_COUNT = 1
  MAX_CLUSTER_COUNT = 2
  INITIALLY_SUSPENDED = TRUE;
A one-off 'just this backfill' run on the BI warehouse is how BI becomes XL again. Resource monitors per warehouse catch it: a monitor on BI_MEDIUM at a daily credit cap suspends a runaway explore without pausing nightly dbt.
Tasks, Snowpipes, and dynamic tables have their own compute stories (serverless tasks bill a different meter). Don't park them on ANALYTICS_XL because it's always up. Always-up is the thing to fix, not a convenience.
After the split, re-run the idle-hour test on both. ETL_LARGE should show blocks of busy hours and real suspend overnight. BI_MEDIUM should show lots of tiny jobs and, if auto-suspend is 60, very little idle tail. If BI_MEDIUM still looks like an XL hour, check the Looker connection first: the dashboards are probably still pointed at the old warehouse.
What to ALTER this week
List warehouses by 30-day credits_used_compute. For the top five, compute idle-hour share, p50 query execution_time, p90 bytes_scanned, and whether cluster_number ever left 1. That one table is the whole meeting.
SELECT warehouse_name,
       SUM(credits_used_compute) AS compute_credits,
       SUM(credits_used_cloud_services) AS cloud_services_credits
FROM snowflake.account_usage.warehouse_metering_history
WHERE start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
GROUP BY 1
ORDER BY 2 DESC;
BI-shaped (short jobs, small bytes, long auto-suspend): set AUTO_SUSPEND = 60, drop a size, and set MIN_CLUSTER_COUNT = 1. ETL-shaped (long jobs, large bytes): leave size alone until prune is fixed, and keep auto-suspend at 5 to 10 minutes so you don't resume-thrash mid-run.
Apply one ALTER per warehouse per day and re-measure. Latency in Looker and dbt runtime are the constraints; credits in WAREHOUSE_METERING_HISTORY are the scoreboard. If a size drop adds queued_load, bump MAX_CLUSTER_COUNT before you bump size back up.
Don't grant a scanner the right to ALTER WAREHOUSE. SlashPeak will recommend; you apply. Join the waitlist on the Snowflake product page if you want the ranked list built from IMPORTED PRIVILEGES without maintaining these joins yourself. The scanner is coming soon; the ALTER WAREHOUSE is available today.
- Idle share high: shorten auto-suspend. Do not resize yet.
- Idle share low, bytes small, size Large+: drop a size and watch queued_load.
- MIN_CLUSTER_COUNT > 1 with cluster_number stuck at 1: drop MIN to 1.
- Shared ETL+BI warehouse: split, then repeat the list.
Takeaways
- Snowflake bills the warehouse while it's resumed. Auto-suspend of 10 minutes is 10 minutes of credits after the last 8-second explore.
- XL for a small scan is a different leak from a prune miss. Measure both; mixing them is how the wrong ALTER ships.
- The idle hour test is WAREHOUSE_METERING_HISTORY credits with no overlapping QUERY_HISTORY. Fail soft on ACCOUNT_USAGE lag.
- 60 seconds is the usual BI auto-suspend. ETL can stay longer. Inter-arrival time is the real setting, not a default copied from a blog.
- MIN_CLUSTER_COUNT > 1 with cluster_number stuck at 1 is a floor you paid for and never used.
- Split ETL and BI warehouses before buying a 2XL. An always-up warehouse is the thing to fix.
- Resource monitors are circuit breakers. They don't replace auto-suspend.
- SlashPeak will rank idle credits separately from query-scan waste so the ALTER WAREHOUSE and the ALTER TABLE don't get mixed. Scanner coming soon, recommend-only, IMPORTED PRIVILEGES only.