Three storage meters on every table
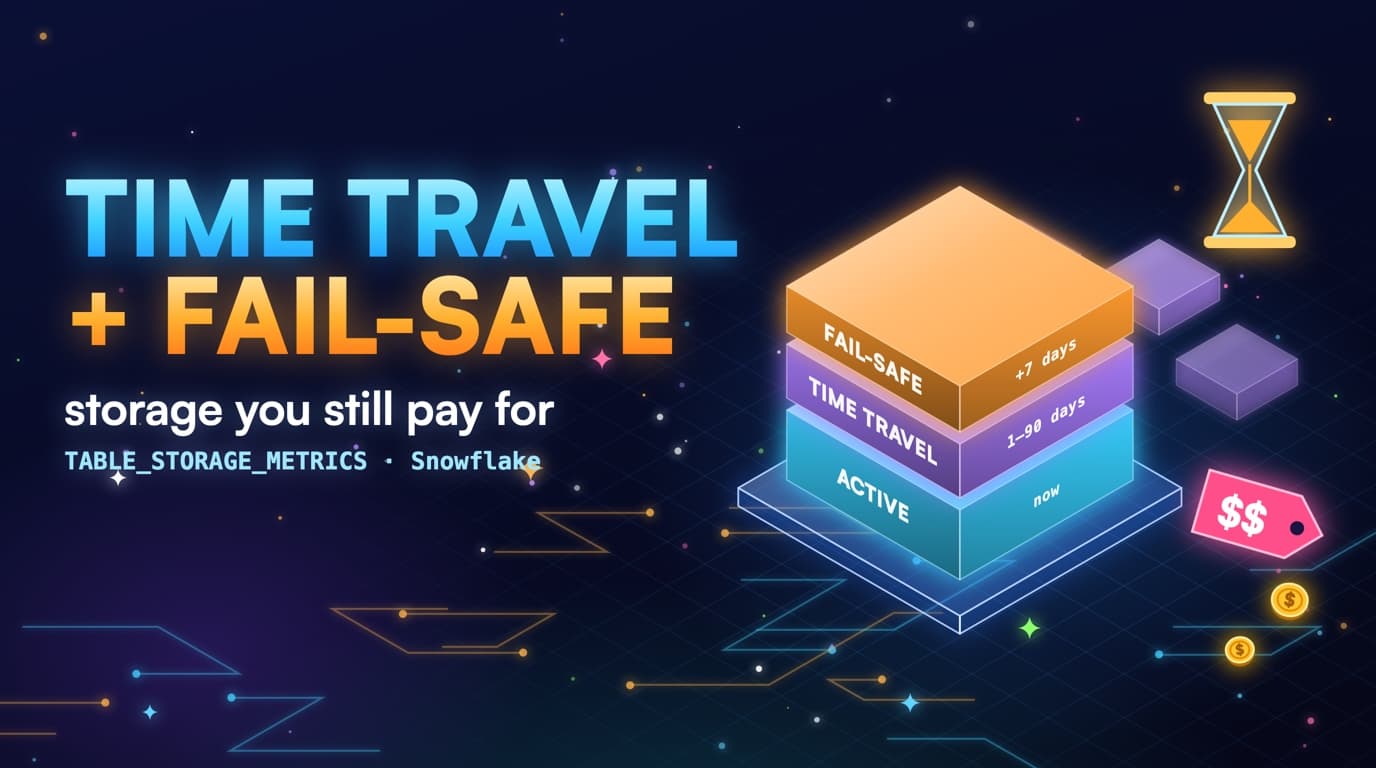
Active storage is the current micro-partitions. Time Travel storage is the previous versions kept for DATA_RETENTION_TIME_IN_DAYS (0 to 90 on Enterprise). Fail-safe is an extra 7 days after Time Travel on permanent tables; you can't query it, but you still pay for it.
TABLE_STORAGE_METRICS.ACTIVE_BYTES, TIME_TRAVEL_BYTES, and FAILSAFE_BYTES are the three columns. A 4 TB table with 14-day retention and heavy MERGE can easily show 4 TB active plus 6 TB Time Travel. The query that rewrote the table already finished; the storage bill didn't.
SELECT table_catalog, table_schema, table_name,
       active_bytes, time_travel_bytes, failsafe_bytes,
       retained_for_clone_bytes, is_transient
FROM snowflake.account_usage.table_storage_metrics
WHERE deleted = FALSE
ORDER BY time_travel_bytes + failsafe_bytes DESC
LIMIT 50;
RETAINED_FOR_CLONE_BYTES is the fourth column people miss. When a clone still needs micro-partitions the source has since rewritten, Snowflake attributes retained bytes so the clone and source don't double-count in a naive SUM, but the account still stores them. Long-lived clones of mutated facts show up here; treat clone-retained bytes as part of the storage story, not as free because the clone was zero-copy.
IS_TRANSIENT on the same view tells you whether Fail-safe should even exist. Transient tables have no Fail-safe and Time Travel capped at 1 day. Temporary tables are session-scoped and shouldn't appear as 90-day account defaults. If a 'scratch' schema is full of permanent tables with 14-day retention, that's an inheritance accident, not a restore strategy.
Storage is usually smaller than warehouse credits, but it's the line that never goes to zero after you stop querying. Compute sleeps; Time Travel doesn't. A table nobody has touched in 40 days still bills active plus Fail-safe until you drop it or change type and retention, which is why last-query time belongs next to TIME_TRAVEL_BYTES on the ranked list.
None of this requires SELECT on the table. TABLE_STORAGE_METRICS, TABLES, and QUERY_HISTORY's last start_time per object (via ACCESS_HISTORY or query_text attribution) are catalog data. IMPORTED PRIVILEGES on SNOWFLAKE is enough.
How a changed row's bytes expire
Active bytes become Time Travel bytes the moment a row is overwritten, then Fail-safe bytes for 7 more days that Snowflake bills but you cannot query.
Retention is a product decision, not a default you forgot
90-day Time Travel on a staging table nobody clones is a gift to the storage line. Dev and ETL landing tables usually want 1 day, or TRANSIENT, which has no Fail-safe and a 1-day Time Travel cap. Production facts that actually get undropped can stay at 7 or 14.
ALTER TABLE ... DATA_RETENTION_TIME_IN_DAYS = 1 is reversible. Fail-safe on a transient table isn't a thing, which is the whole point of transient.
ALTER TABLE staging.events_raw SET DATA_RETENTION_TIME_IN_DAYS = 1;

CREATE TRANSIENT TABLE staging.scratch_orders
  DATA_RETENTION_TIME_IN_DAYS = 1
  AS SELECT * FROM staging.orders_today;
-- Transient: no Fail-safe. Time Travel capped at 1 day.
Retention inherits: account default, then schema, then table. A Terraform-created schema that doesn't set DATA_RETENTION_TIME_IN_DAYS picks up the account default, which on Enterprise is often 1 or 7 until someone sets 90 'for compliance' in a panic after a bad drop. Compliance is a table-level conversation; staging.events_raw isn't the same object as analytics.ledger.
SELECT catalog_name, schema_name, retention_time
FROM snowflake.account_usage.schemata
WHERE deleted IS NULL
ORDER BY retention_time DESC NULLS LAST, schema_name;

SELECT table_schema, table_name, retention_time, is_transient
FROM snowflake.account_usage.tables
WHERE deleted IS NULL
  AND table_type = 'BASE TABLE'
ORDER BY retention_time DESC NULLS LAST, bytes DESC NULLS LAST
LIMIT 100;
Time Travel is queryable (SELECT ... AT TIMESTAMP / BEFORE STATEMENT). Fail-safe isn't: it's a Snowflake-operated recovery window after retention expires, billed to you, usable only via Support. If your runbook never calls Support to recover a staging table, you don't want Fail-safe on that table. Transient is how you opt out.
Zero-day retention is allowed on some editions and is the right call for true scratch, but know the blast radius: UNDROP won't save you. If the table is re-creatable from a pipeline, zero or one day is enough. If it's a ledger with no upstream, keep enough Time Travel that a bad MERGE can be reversed, and accept the storage cost.
Change retention in steps on huge tables. Dropping 90 to 1 doesn't instantly delete 89 days of versions; Snowflake expires them over time, and Fail-safe may still catch some bytes. Re-read TABLE_STORAGE_METRICS a few days later rather than declaring victory the afternoon of the ALTER.
How Time Travel keeps old partitions alive in a clone
Zero-copy clone is cheap at CREATE time. Then the source table MERGE-rewrites partitions and Time Travel holds the pre-clone bytes on both the clone and the source. Long-lived clones of frequently mutated tables are a storage leak that started as 'we cloned for a ticket.'
Drop clones you aren't using, and shorten retention on tables that clone often. Don't keep a 90-day clone of a CDC fact just in case.
CREATE TABLE ... CLONE is the Dev/QA pattern Snowflake got right. The anti-pattern is a clone per Jira ticket that nobody drops, pointing at analytics.orders, living for a quarter while orders MERGEs every hour. RETAINED_FOR_CLONE_BYTES and extra TIME_TRAVEL_BYTES are the bill; the clone name still says scratch.
Clones inherit retention settings unless you ALTER them, so a clone of a 90-day fact is a 90-day fact. Set DATA_RETENTION_TIME_IN_DAYS = 1 on the clone the day you create it if it isn't a recovery object. Better still, clone from a transient staging table that already has 1-day retention.
ACCOUNT_USAGE.TABLE_STORAGE_METRICS includes clone_group_id and id. Tables sharing a clone group are the family; sum storage across the family before calling a Dev environment free. DATABASE_STORAGE_USAGE_HISTORY shows the database-level lump if you cloned a whole database.
A clone keeps partitions the source already rewrote
Zero-copy is cheap only at create time. Once the source mutates, the clone's old partitions stay retained until both the clone and the source agree they are gone.
- Active: current table. Time Travel: versions you can undrop or select-at. Fail-safe: 7 days you can't query.
- Transient skips Fail-safe. Temporary tables never belong in a 90-day account default.
- Clones share partitions until writes plus Time Travel duplicate them.
Storage waste is a ranked list too
Join TABLE_STORAGE_METRICS to QUERY_HISTORY: a table with huge Time Travel and no queries in 30 days is drop-or-transient. A table queried hourly with 90-day retention is a conversation with whoever owns undrop. You apply the ALTER; nothing auto-drops.
Last query time is approximate, from ACCESS_HISTORY or query_text matching, and it will be wrong sometimes. Don't recommend DROP on a table you can't prove is unused. Do recommend shortening retention when TIME_TRAVEL_BYTES dwarfs ACTIVE_BYTES on a staging schema, even if someone queried it yesterday; yesterday's query doesn't need 90 days of versions behind it.
Deleted tables still appear with deleted = TRUE and can still hold Fail-safe bytes. Include them in the ranked list. A DROP TABLE on Friday with 14-day retention plus Fail-safe is three weeks of paying for a table that's gone from every workbook. Fine for a ledger, not fine for last week's experiment.
Database- and account-level STORAGE_USAGE / DATABASE_STORAGE_USAGE_HISTORY give you the trend; TABLE_STORAGE_METRICS gives you the action. Start from the table view. A trend line with no table list is a finance conversation with no ticket attached.
SlashPeak will rank TIME_TRAVEL_BYTES plus FAILSAFE_BYTES against last query time and table type once the Snowflake scanner ships, with the same conservative skip when ACCOUNT_USAGE lags. Metadata only, recommend-only; you apply the ALTER or the DROP.
MERGE-heavy facts amplify Time Travel
Every MERGE that rewrites micro-partitions creates a previous version those partitions keep for DATA_RETENTION_TIME_IN_DAYS. A table that MERGEs 10% of rows every hour with 14-day retention isn't just 14 days of extra storage; it's many overlapping versions of those partitions. TIME_TRAVEL_BYTES larger than ACTIVE_BYTES is the tell.
SELECT table_schema, table_name,
       active_bytes,
       time_travel_bytes,
       failsafe_bytes,
       DIV0(time_travel_bytes, NULLIF(active_bytes, 0)) AS tt_to_active
FROM snowflake.account_usage.table_storage_metrics
WHERE deleted = FALSE
  AND time_travel_bytes > active_bytes
ORDER BY time_travel_bytes DESC
LIMIT 50;
Incremental merges that prune the target (ON includes the clustering or date column) rewrite fewer partitions and retain fewer old ones, so the prune fix and the storage fix are the same table. Fixing MERGE ON order_date cuts warehouse credits and Time Travel bytes together.
Full-table rebuilds (CREATE OR REPLACE TABLE AS, or INSERT OVERWRITE) also create versions. A CTAS replace with 90-day retention on a 4 TB fact is a storage event on its own. Prefer SWAP with a transient build table if you must rebuild, and keep retention low on that build table.
CREATE OR REPLACE TRANSIENT TABLE analytics.orders_rebuild
  DATA_RETENTION_TIME_IN_DAYS = 1
  AS SELECT * FROM analytics.orders_src;

ALTER TABLE analytics.orders SWAP WITH analytics.orders_rebuild;
DROP TABLE analytics.orders_rebuild;
If the business truly needs 14-day UNDROP on that fact, pay for it with eyes open: put the number next to the warehouse credits rather than discovering it as 'storage went up after we made dbt incremental' without ever looking at TABLE_STORAGE_METRICS.
A pruned MERGE keeps fewer old versions too
A MERGE that rewrites partitions across the whole table also keeps more old versions in Time Travel. Bounding the target to recent partitions shrinks both bills at once.
Transient, temporary, and permanent: three Fail-safe stories
Permanent: Time Travel up to your edition cap, then 7 days of Fail-safe. The default for CREATE TABLE, and correct for data you can't rebuild and might UNDROP.
Transient: Time Travel at most 1 day, no Fail-safe. Correct for staging, scratch, ETL landing, and most Dev clones. Use CREATE TRANSIENT TABLE or ALTER to recreate, since you can't always flip the type in place; plan the cutover.
SELECT table_schema, table_name, is_transient, retention_time, bytes
FROM snowflake.account_usage.tables
WHERE deleted IS NULL
  AND table_type = 'BASE TABLE'
  AND table_schema ILIKE '%STAG%'
  AND (is_transient = 'NO' OR is_transient = FALSE)
ORDER BY bytes DESC NULLS LAST;
Temporary: session-scoped. These should never be the account default and never the 8 TB fact. If a BI tool is creating permanent tables in a user sandbox because a worksheet omitted TEMPORARY, that's a governance finding as much as a storage one.
External tables and Iceberg tables have different storage bills tied to your object store, so don't apply Fail-safe assumptions to them. TABLE_STORAGE_METRICS still covers native tables, which is where this post's dollars live.
A practical default: account retention 1 day, production schemas 7, staging schemas transient with 1, scratch schemas transient with 1 or 0, then exceptions for ledgers. Keep the exception list short enough to read in standup.
Three table types, three Fail-safe outcomes
The table type decides whether Fail-safe even exists. Staging and scratch rarely need it; a true ledger usually does.
Clone sprawl from ACCOUNT_USAGE
Look for tables whose names contain clone, scratch, tmp, backup, or _copy, with material retained_for_clone_bytes or time_travel_bytes, and last DDL older than a sprint. That heuristic is blunt, but it works. Pair it with clone_group_id so you drop children before breaking a family you still need.
SELECT clone_group_id,
       COUNT(*) AS tables_in_family,
       SUM(active_bytes) AS active_bytes,
       SUM(time_travel_bytes) AS time_travel_bytes,
       SUM(retained_for_clone_bytes) AS retained_for_clone_bytes
FROM snowflake.account_usage.table_storage_metrics
WHERE deleted = FALSE
GROUP BY 1
HAVING COUNT(*) > 1
ORDER BY retained_for_clone_bytes DESC NULLS LAST
LIMIT 50;
Whole-database clones for Dev are legitimate; monthly database clones everyone forgot about are not. DATABASE_STORAGE_USAGE_HISTORY by database_name, ranked descending, is the slide for that conversation. If DEV_2026_03 is still in the top five storage databases in August, drop it or rebuild it as transient.
SELECT database_name,
       DATE_TRUNC('day', usage_date) AS day,
       MAX(average_database_bytes) AS database_bytes,
       MAX(average_failsafe_bytes) AS failsafe_bytes
FROM snowflake.account_usage.database_storage_usage_history
WHERE usage_date >= DATEADD(day, -30, CURRENT_DATE())
GROUP BY 1, 2
ORDER BY 3 DESC;
CLONE at the schema level plus 90-day retention is how a quick prod copy becomes a second prod storage bill once the source mutates. Set retention on the clone at create time, and put an expiration in the clone name plus a calendar reminder; Snowflake won't expire it for you.
You still never SELECT user data to do this audit. Names, bytes, DDL timestamps, and clone ids are all catalog data. SlashPeak will rank this class of finding as storage, owned by the schema, not as query waste.
What to ALTER and drop this week
Rank TABLE_STORAGE_METRICS by time_travel_bytes plus failsafe_bytes, and tag each row: production fact, staging, clone, deleted, unknown. Unknown stays off the DROP list.
Staging and scratch: set DATA_RETENTION_TIME_IN_DAYS = 1 and plan a transient cutover. Clones older than a sprint: drop or shorten retention. Deleted rows still billing Fail-safe: note the date, and don't UNDROP just to save storage.
Production facts with TIME_TRAVEL_BYTES much larger than ACTIVE_BYTES: fix the MERGE prune and consider retention 7 instead of 90 if UNDROP policy allows. Get the owner into the ticket; storage findings without owners don't ship.
Re-read metrics after ACCOUNT_USAGE lag. Join the SlashPeak waitlist if you want this ranked next to idle warehouses and prune misses on the same 30-day window. The scanner is coming soon, IMPORTED PRIVILEGES only, recommend-only. The ALTER TABLE is available today.
- Never DROP based on TIME_TRAVEL_BYTES alone. Prove the table is unused or prove it's staging.
- Transient is the Fail-safe opt-out. Retention days are the Time Travel knob.
- Clones need an expiry. Zero-copy isn't zero-storage once the source mutates.
- SlashPeak won't drop tables. You apply every destructive change.
Takeaways
- Time Travel and Fail-safe are storage meters, not free undo. 90-day retention on staging is usually accidental.
- TABLE_STORAGE_METRICS splits active, Time Travel, Fail-safe, and clone-retained bytes. Start there, not from the invoice lump.
- Transient tables skip Fail-safe and cap Time Travel at 1 day. Use them for staging and scratch.
- Long-lived clones of mutated facts quietly duplicate partitions. RETAINED_FOR_CLONE_BYTES is the tell.
- MERGE that rewrites random partitions inflates Time Travel. Prune the target and you cut storage too.
- Retention inherits from account to schema to table. Set it where the restore policy actually lives.
- SlashPeak will rank Time Travel bytes next to last query time so storage findings have an owner.
- Scanner coming soon: metadata-only, recommend-only. You ALTER retention, recreate transient tables, and drop clones. Nothing auto-drops.