On BigQuery
AvailablePartition filters from job_stages, unpartitioned date scans, SELECT * over-fetch, CTE re-scans, and MERGE target rewrites — live in the 23-rule engine today.
BigQuery productMost bills come from a few queries that look filtered in SQL and still read everything. We rank them by monthly cost and show the filter, cluster key or column list that would have skipped the rest.
Partition filters from job_stages, unpartitioned date scans, SELECT * over-fetch, CTE re-scans, and MERGE target rewrites — live in the 23-rule engine today.
BigQuery productComing soon: micro-partition prune misses, wrap-the-column filters, SELECT * over-fetch, and warehouse-credit waste from queries that never pruned.
Snowflake productComing soon: Delta full scans, missing partition filters, SELECT * on wide tables, and Photon shuffle-heavy jobs from system.query.history.
Databricks product30 to 90 days of jobs (by plan), plans, and bytes or slot time — never table contents.
Each finding names the table, the missed predicate, and a sample query.
You apply the change, or the Cognis AI DBA opens a pull request. The next scan is the scoreboard.
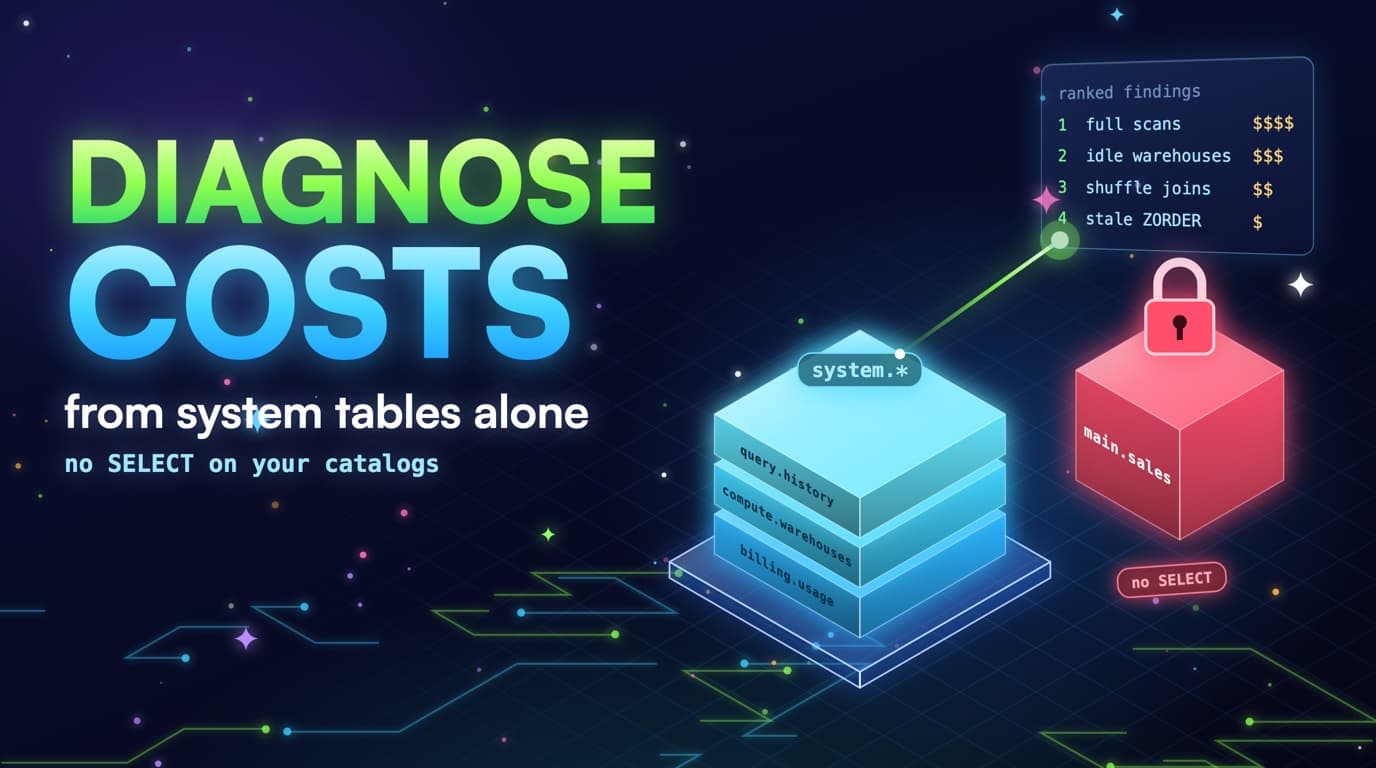
system.query.history and system.compute.warehouses rank full scans, idle warehouses, and shuffle-heavy jobs. SlashPeak never needs SELECT on your tables.
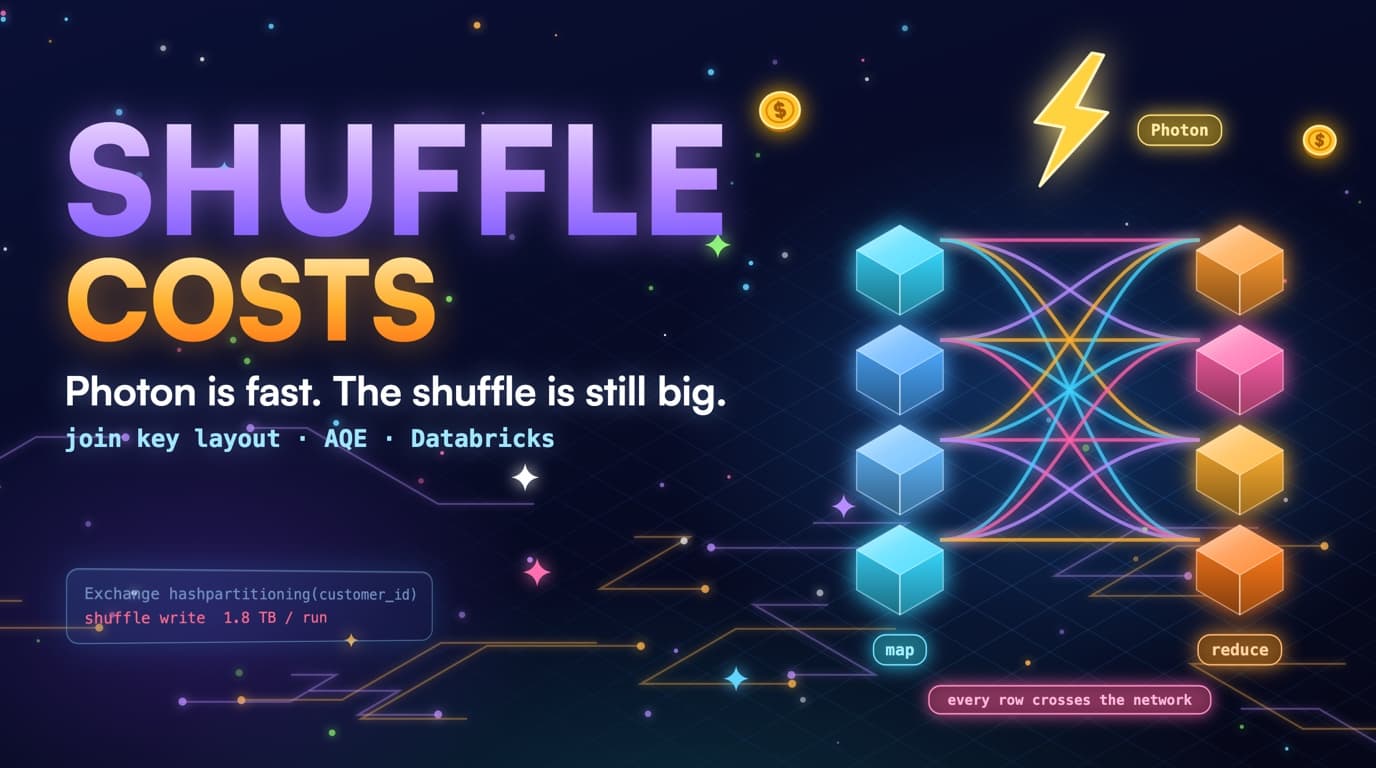
Photon speeds up a shuffle join; it does not shrink it. Adaptive execution helps at the edges, but an unclustered join key still burns DBUs every run.
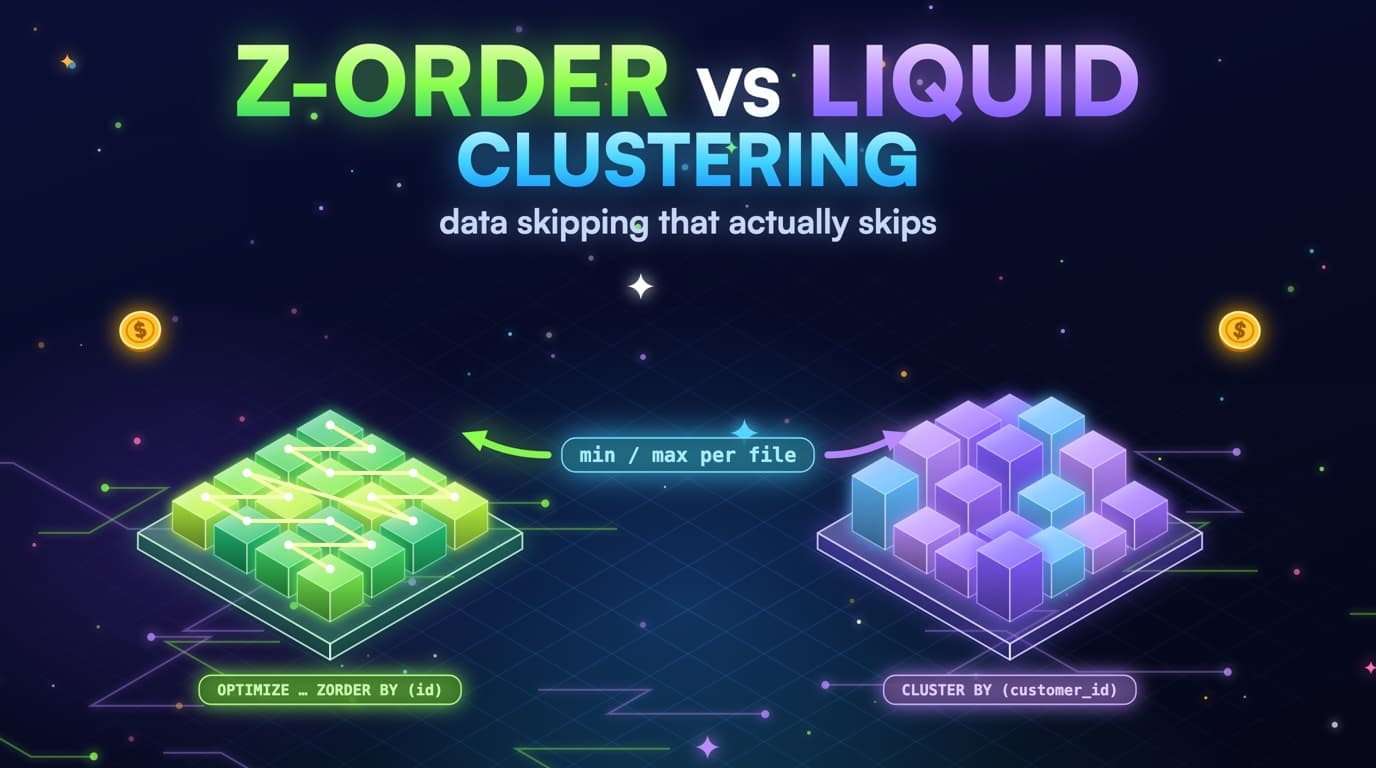
ZORDER and liquid clustering write min/max stats so Photon can skip files. The wrong columns, or a stale table, means it still reads everything.
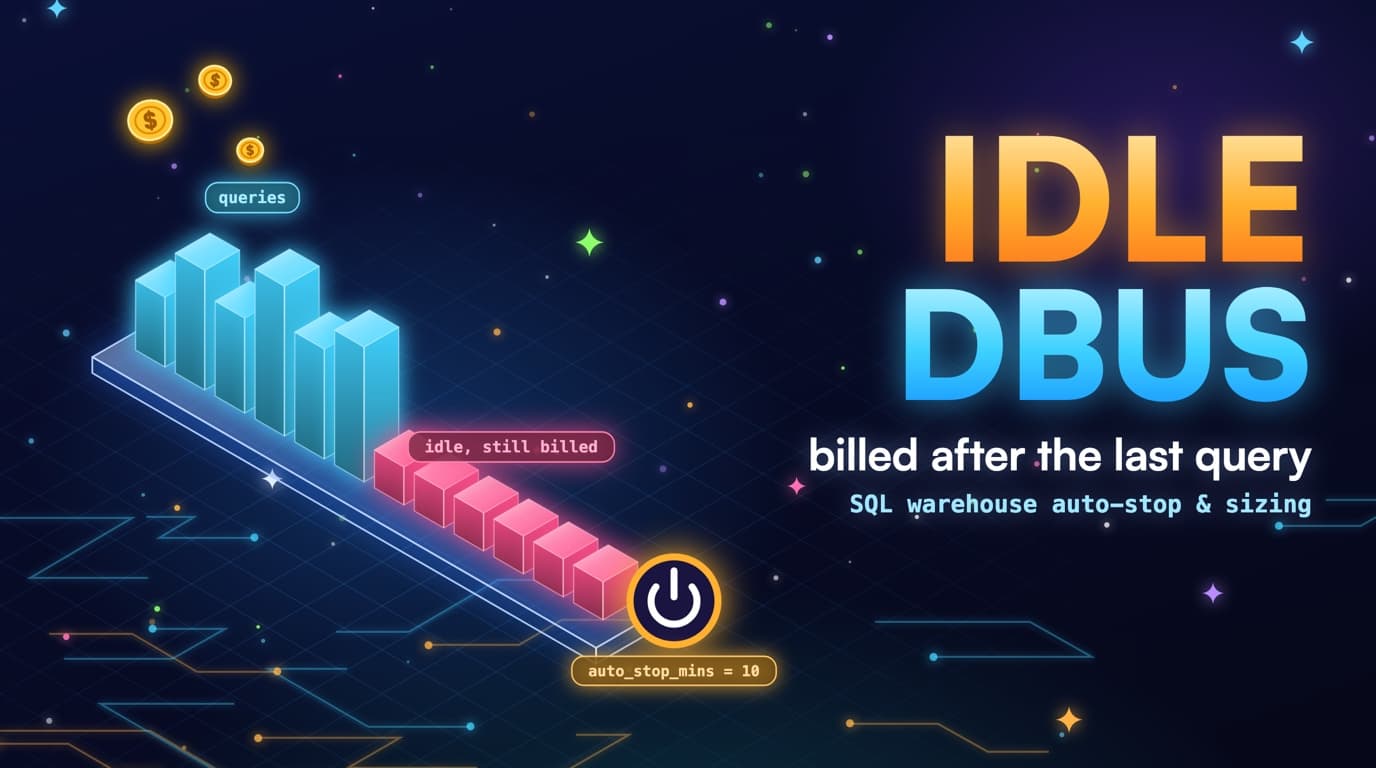
A serverless warehouse with a 10-minute auto-stop bills 10 minutes after the last query. Oversizing is a separate leak, and system tables show both.
Understand, reduce and govern your cloud data spend with SlashPeak — starting today.